TurboQuant: Redefining AI efficiency with extreme compression
research.google
March 25, 2026
7 min read
🔥🔥🔥🔥🔥
68/100
Summary
TurboQuant introduces advanced quantization algorithms that facilitate significant compression of large language models and vector search engines. These algorithms enhance AI efficiency by optimizing how models process and understand information through vector representation.
Key Takeaways
- TurboQuant is a new compression algorithm that achieves significant model size reduction without any accuracy loss, enhancing both key-value cache compression and vector search efficiency.
- The algorithm employs PolarQuant for high-quality compression and the Quantized Johnson-Lindenstrauss (QJL) method to eliminate residual errors, ensuring optimal performance.
- TurboQuant addresses memory overhead issues commonly associated with traditional vector quantization methods, making it suitable for large language models and search engines.
- Testing of TurboQuant, QJL, and PolarQuant demonstrated their effectiveness in reducing key-value bottlenecks while maintaining AI model performance.
Coverage & discussions
Hacker News · research.google
Community discussions
Community Sentiment
Positives
- The development of TurboQuant for KV cache compression represents a significant advancement in AI efficiency, potentially improving performance in resource-constrained environments.
Concerns
- The explanation of TurboQuant lacks clarity, making it difficult for non-experts to grasp its significance and implications in AI applications.
- There is a noticeable disconnect between the technical details in the paper and the blog post, highlighting a need for more accessible communication from research teams.
- The absence of proper citations in the discussion raises concerns about academic rigor and acknowledgment of foundational work in AI compression techniques.
Related Articles
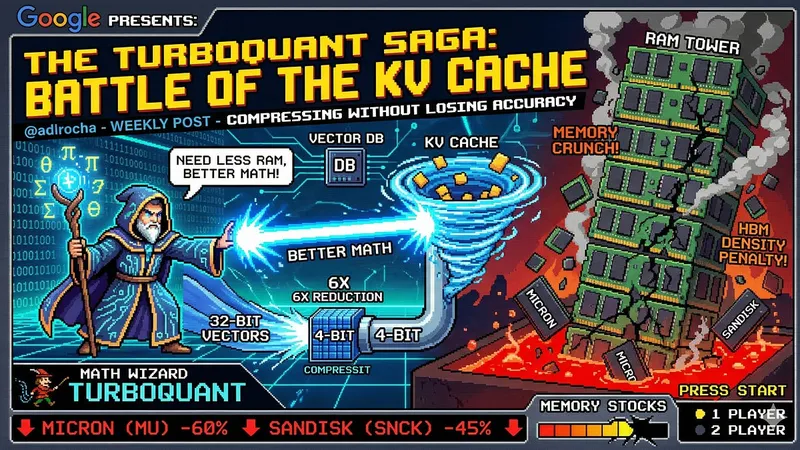
What if AI doesn't need more RAM but better math?
Mar 29, 2026
TurboQuant: A first-principles walkthrough
Apr 27, 2026
Turbovec – Google's TurboQuant for vector search in Rust
Aug 18, 2026
TurboQuant KV Compression and SSD Expert Streaming for M5 Pro and IOS
Apr 1, 2026
Smaller, faster, safer: running Kimi and GLM at scale
Aug 3, 2026