AMD acquires Taalas to boost inference performance by etching models in silicon
AMD has acquired AI chip startup Taalas to enhance inference performance by etching AI models directly into silicon. Early tech demos demonstrate that these model-specific integrated circuits can process up to 17,000 tokens per second.
theregister.com
1 min
8/6/2026
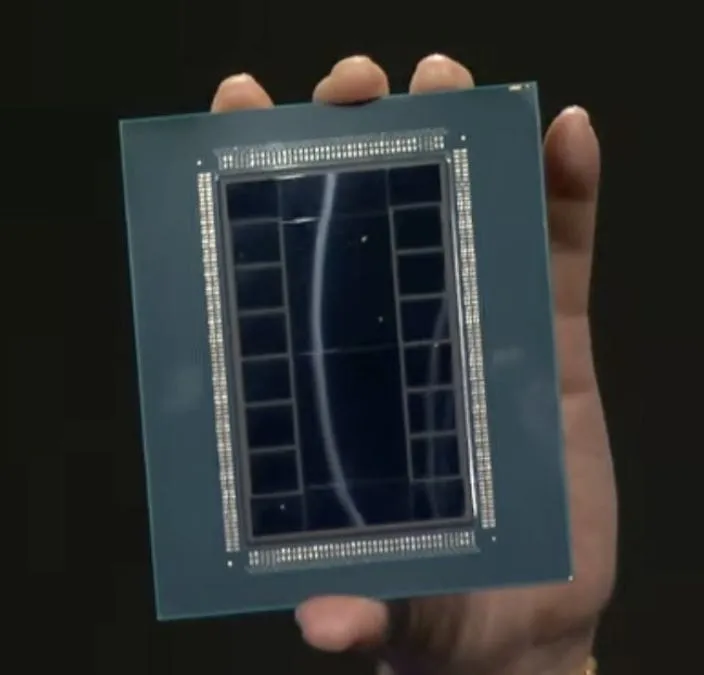
Performance per dollar is getting faster and cheaper
Performance per dollar for AI inference is improving, with GLM5.2 served on AMD MI355X achieving 2626 tokens per second per node and 213 tokens per second in a single stream at over 2x lower cost than Blackwell. Demand for inference is increasing rapidly, outpacing supply, as new frontier models are released frequently.
wafer.ai
5 min
7/3/2026
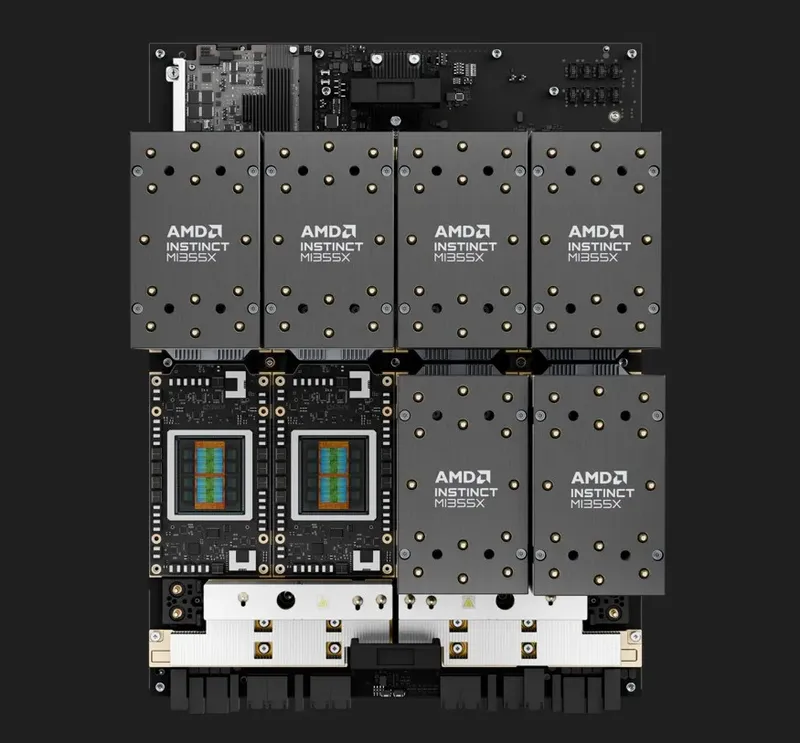
AMD Ryzen AI NPUs are finally useful under Linux for running LLMs
AMD has developed the AMDXDNA accelerator driver for the mainline Linux kernel to support AMD Ryzen AI NPUs. User-space software for effectively utilizing these NPUs on Linux has been limited, with most applications relying on iGPU support instead.
phoronix.com
4 min
3/11/2026
AMD acquires Taalas to boost inference performance by etching models in silicon
AMD has acquired AI chip startup Taalas to enhance inference performance by etching AI models directly into silicon. Early tech demos demonstrate that these model-specific integrated circuits can process up to 17,000 tokens per second.
theregister.com
1 min
8/6/2026
Performance per dollar is getting faster and cheaper
Performance per dollar for AI inference is improving, with GLM5.2 served on AMD MI355X achieving 2626 tokens per second per node and 213 tokens per second in a single stream at over 2x lower cost than Blackwell. Demand for inference is increasing rapidly, outpacing supply, as new frontier models are released frequently.
wafer.ai
5 min
7/3/2026
AMD Ryzen AI NPUs are finally useful under Linux for running LLMs
AMD has developed the AMDXDNA accelerator driver for the mainline Linux kernel to support AMD Ryzen AI NPUs. User-space software for effectively utilizing these NPUs on Linux has been limited, with most applications relying on iGPU support instead.
phoronix.com
4 min
3/11/2026
Scrying the AMD GFX1250 LLVM Tea Leaves
AMD will showcase the new MI400 series of Datacenter Accelerators, including the GFX1250 and GFX1251, at their Advancing AI event. LLVM has begun preliminary support for these two new accelerators.
chipsandcheese.com
15 min
7/19/2026
AMD acquires Taalas to boost inference performance by etching models in silicon
AMD has acquired AI chip startup Taalas to enhance inference performance by etching AI models directly into silicon. Early tech demos demonstrate that these model-specific integrated circuits can process up to 17,000 tokens per second.
theregister.com
1 min
8/6/2026
Scrying the AMD GFX1250 LLVM Tea Leaves
AMD will showcase the new MI400 series of Datacenter Accelerators, including the GFX1250 and GFX1251, at their Advancing AI event. LLVM has begun preliminary support for these two new accelerators.
chipsandcheese.com
15 min
7/19/2026
AMD Ryzen AI NPUs are finally useful under Linux for running LLMs
AMD has developed the AMDXDNA accelerator driver for the mainline Linux kernel to support AMD Ryzen AI NPUs. User-space software for effectively utilizing these NPUs on Linux has been limited, with most applications relying on iGPU support instead.
phoronix.com
4 min
3/11/2026
Performance per dollar is getting faster and cheaper
Performance per dollar for AI inference is improving, with GLM5.2 served on AMD MI355X achieving 2626 tokens per second per node and 213 tokens per second in a single stream at over 2x lower cost than Blackwell. Demand for inference is increasing rapidly, outpacing supply, as new frontier models are released frequently.
wafer.ai
5 min
7/3/2026
No more articles to load