Auto-research with codex: How I achieved a 232x Faster Kernel
Codex was utilized to achieve a 232x faster kernel for the qr_v2 problem in GPU mode. The implementation involved optimizing the blocked Householder algorithm and introducing idea diversity to enhance performance.
sankalp.bearblog.dev
26 min
8/15/2026
MegaTrain: Full Precision Training of 100B+ Parameter LLMs on a Single GPU
MegaTrain is a memory-centric system that enables the full precision training of large language models with over 100 billion parameters on a single GPU. It utilizes host memory to store parameters and optimizer states, treating GPUs as transient computation units.
arxiv.org
2 min
4/8/2026
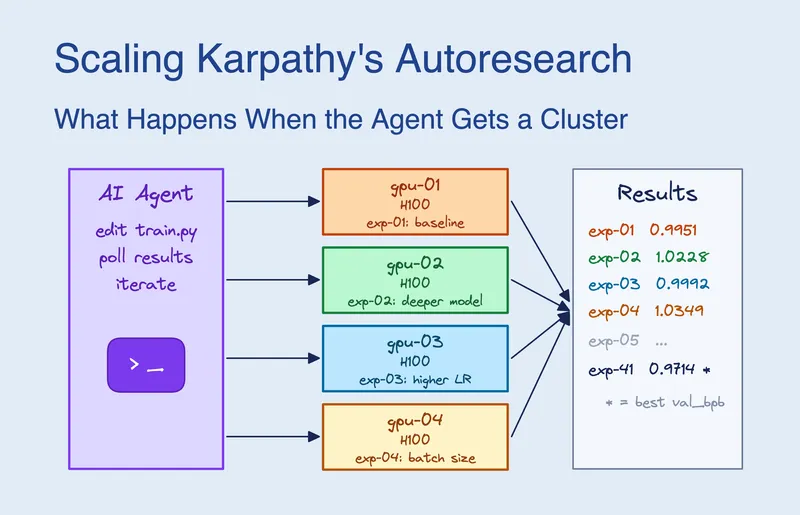
Scaling Karpathy's Autoresearch: What Happens When the Agent Gets a GPU Cluster
Claude Code was given access to 16 GPUs on a Kubernetes cluster and submitted approximately 910 experiments over 8 hours. It determined that scaling model width was more significant than any single hyperparameter and achieved a 2.87% improvement in validation performance, reducing val_bpb from 1.003 to 0.974.
blog.skypilot.co
12 min
3/19/2026
Auto-research with codex: How I achieved a 232x Faster Kernel
Codex was utilized to achieve a 232x faster kernel for the qr_v2 problem in GPU mode. The implementation involved optimizing the blocked Householder algorithm and introducing idea diversity to enhance performance.
sankalp.bearblog.dev
26 min
8/15/2026
Scaling Karpathy's Autoresearch: What Happens When the Agent Gets a GPU Cluster
Claude Code was given access to 16 GPUs on a Kubernetes cluster and submitted approximately 910 experiments over 8 hours. It determined that scaling model width was more significant than any single hyperparameter and achieved a 2.87% improvement in validation performance, reducing val_bpb from 1.003 to 0.974.
blog.skypilot.co
12 min
3/19/2026
MegaTrain: Full Precision Training of 100B+ Parameter LLMs on a Single GPU
MegaTrain is a memory-centric system that enables the full precision training of large language models with over 100 billion parameters on a single GPU. It utilizes host memory to store parameters and optimizer states, treating GPUs as transient computation units.
arxiv.org
2 min
4/8/2026
Auto-research with codex: How I achieved a 232x Faster Kernel
Codex was utilized to achieve a 232x faster kernel for the qr_v2 problem in GPU mode. The implementation involved optimizing the blocked Householder algorithm and introducing idea diversity to enhance performance.
sankalp.bearblog.dev
26 min
8/15/2026
MegaTrain: Full Precision Training of 100B+ Parameter LLMs on a Single GPU
MegaTrain is a memory-centric system that enables the full precision training of large language models with over 100 billion parameters on a single GPU. It utilizes host memory to store parameters and optimizer states, treating GPUs as transient computation units.
arxiv.org
2 min
4/8/2026
Scaling Karpathy's Autoresearch: What Happens When the Agent Gets a GPU Cluster
Claude Code was given access to 16 GPUs on a Kubernetes cluster and submitted approximately 910 experiments over 8 hours. It determined that scaling model width was more significant than any single hyperparameter and achieved a 2.87% improvement in validation performance, reducing val_bpb from 1.003 to 0.974.
blog.skypilot.co
12 min
3/19/2026
No more articles to load