Auto-research with codex: How I achieved a 232x Faster Kernel
sankalp.bearblog.dev
August 15, 2026
26 min read
🔥🔥🔥🔥🔥
66/100
Summary
Codex was utilized to achieve a 232x faster kernel for the qr_v2 problem in GPU mode. The implementation involved optimizing the blocked Householder algorithm and introducing idea diversity to enhance performance.
Key Takeaways
- The author achieved a 232x speedup over the baseline solution in a GPU Mode contest focused on batched square compact-Householder QR factorization.
- The contest allowed participants to make unlimited submissions, facilitating rapid iteration and learning through feedback on performance.
- The problem involved implementing QR decomposition for batched square FP32 CUDA matrices, requiring the return of a compact Householder QR representation.
- The author made over 1500 submissions during the 14-day contest, emphasizing the importance of tight feedback loops in optimizing GPU kernels.
Community Sentiment
Positives
- The ability to leverage LLMs for kernel optimization is a game-changer, with users reporting up to 232x speed improvements in their projects.
- DeepSeek v4 is proving itself as a reliable partner for optimizing complex tasks, making previously daunting benchmarks feel approachable and achievable.
- Several commenters are excited about the potential of AI agents to tackle well-defined optimization problems, indicating a significant leap in developer productivity.
Concerns
- There's a clear concern that many AI-generated solutions are overfitting to specific inputs, leading to brittle code that fails under varied conditions.
- Commenters worry about the lack of generality in the AI-generated code, emphasizing that while speed is prioritized, maintainability and robustness are often sacrificed.
- One user noted that while LLMs excel in specific optimizations, they struggle to create general solutions, highlighting limitations in current AI approaches.
Related Articles
LLM Neuroanatomy II: Modern LLM Hacking and Hints of a Universal Language?
Mar 24, 2026
Local Qwen isn't a worse Opus, it's a different tool
Jun 18, 2026
Autoresearch on an old research idea
Mar 23, 2026
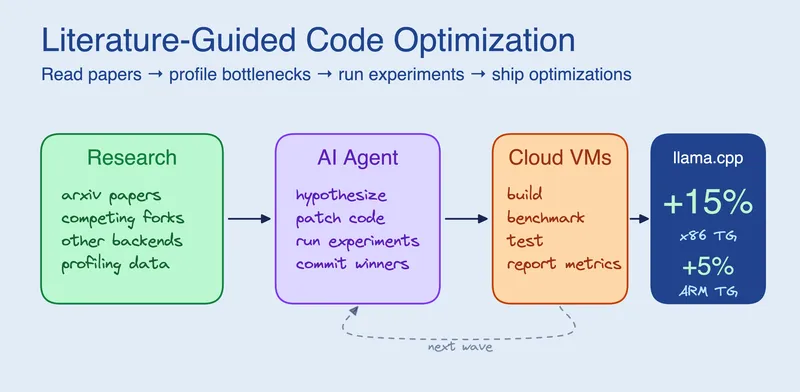
Research-Driven Agents: When an agent reads before it codes
Apr 9, 2026
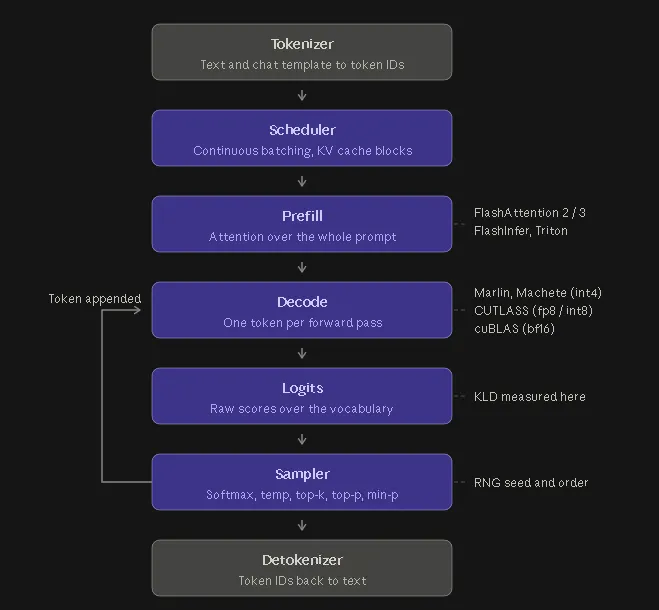
Why your local LLM feels dumber than it is
Aug 22, 2026