Models Are Getting Dumber on Purpose
Reasoning scores for AI models are increasing while per-token compute is decreasing. GLM-5.2 achieves 99.2% on AIME 2026 with 40 billion parameters, Qwen3.5 scores 91.3% with 17 billion parameters, and DeepSeek V4-Flash operates with 13 billion parameters, contrasting with GPT-4's rumored 280 billion parameters which struggled with AIME problems.
w4g1.dev
6 min
8/16/2026
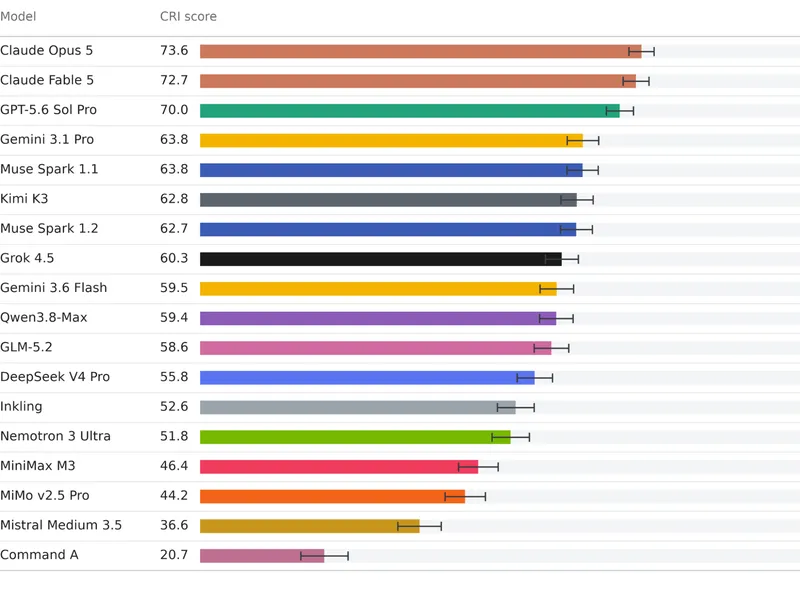
Anthropic: Introducing The Conceptual Reasoning Index
The Conceptual Reasoning Index introduces a suite of three benchmarks to evaluate AI capabilities in understanding situations, planning for the future, and developing risk mitigations. Access to the primary conceptual dataset, LMCA, is available upon request.
alignment.anthropic.com
6 min
8/13/2026
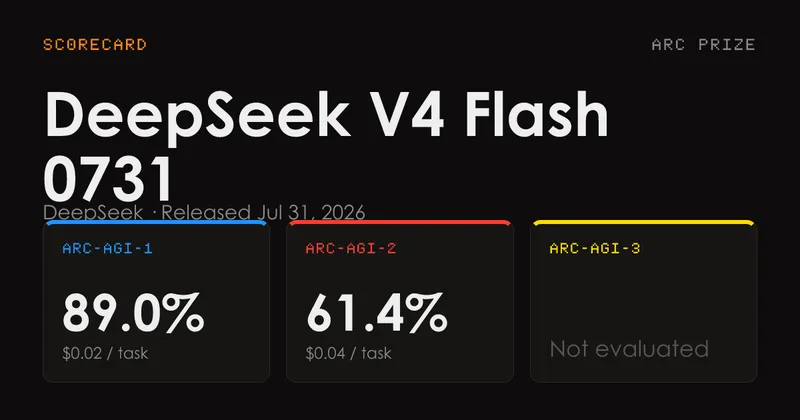
DeepSeek V4 Flash 0731
DeepSeek V4 Flash 0731 achieves scores of 89.0% on ARC-AGI-1 Semi-Private at a cost of $0.02 per task and 61.4% on ARC-AGI-2 Semi-Private at $0.04 per task. The model also records scores of 87.0% and 56.0% for the High variant, and 84.0% and 46.0% for the Low variant on the respective benchmarks.
arcprize.org
21 min
8/7/2026
When AI Benchmarks Plateau: A Systematic Study of Benchmark Saturation
AI benchmarks are essential for assessing model performance and informing deployment choices. However, they often reach saturation, reducing their effectiveness in distinguishing between models and limiting their long-term utility.
arxiv.org
2 min
8/4/2026
What's the largest software project AI can complete on its own?
MirrorCode is a benchmark designed to evaluate AI models on long-horizon coding tasks by requiring them to reimplement entire programs end-to-end without access to the original source code. Solutions generated by AI must match the output of the original program to be considered successful.
epoch.ai
4 min
8/3/2026
Any text-to-SQL benchmark should address difficulties of real-world data stores
Text-to-SQL benchmarks must consider the complexities and challenges posed by real-world data stores. Effective evaluation should include factors like data variability, schema complexity, and query performance.
cacm.acm.org
1 min
7/22/2026

Are AI Labs Pelicanmaxxing?
Simon Willison has tested major LLM releases using the prompt “Generate an SVG of a pelican riding a bicycle,” creating an informal benchmark in AI. The results often receive significant engagement on platforms like Hacker News, sparking discussions about the benchmark's usefulness.
dylancastillo.co
11 min
7/22/2026

Kimi K3, and what we can still learn from the pelican benchmark
Moonshot AI has launched Kimi K3, their most capable model to date with 2.8 trillion parameters. It is currently accessible via their website and API, with an open weight release scheduled for July 27, 2026.
simonwillison.net
6 min
7/17/2026
The gap between open weights LLMs and closed source LLMs
A prediction indicates that a new Frontier Open Source LLM will be released on December 3, 2026. The analysis compares the performance gap between open weights and closed source LLMs by examining historical benchmarks.
blog.doubleword.ai
2 min
6/26/2026
GLM-5.2 is the new leading open weights model on Artificial Analysis
GLM-5.2 has become the leading open weights model on the Artificial Analysis Intelligence Index, scoring 51. It matches the size of GLM-5.1 with 744 billion total parameters and 40 billion active parameters, but surpasses it by 11 points in the Intelligence Index v4.1.
artificialanalysis.ai
3 min
6/17/2026
Models Are Getting Dumber on Purpose
Reasoning scores for AI models are increasing while per-token compute is decreasing. GLM-5.2 achieves 99.2% on AIME 2026 with 40 billion parameters, Qwen3.5 scores 91.3% with 17 billion parameters, and DeepSeek V4-Flash operates with 13 billion parameters, contrasting with GPT-4's rumored 280 billion parameters which struggled with AIME problems.
w4g1.dev
6 min
8/16/2026
DeepSeek V4 Flash 0731
DeepSeek V4 Flash 0731 achieves scores of 89.0% on ARC-AGI-1 Semi-Private at a cost of $0.02 per task and 61.4% on ARC-AGI-2 Semi-Private at $0.04 per task. The model also records scores of 87.0% and 56.0% for the High variant, and 84.0% and 46.0% for the Low variant on the respective benchmarks.
arcprize.org
21 min
8/7/2026
What's the largest software project AI can complete on its own?
MirrorCode is a benchmark designed to evaluate AI models on long-horizon coding tasks by requiring them to reimplement entire programs end-to-end without access to the original source code. Solutions generated by AI must match the output of the original program to be considered successful.
epoch.ai
4 min
8/3/2026
Are AI Labs Pelicanmaxxing?
Simon Willison has tested major LLM releases using the prompt “Generate an SVG of a pelican riding a bicycle,” creating an informal benchmark in AI. The results often receive significant engagement on platforms like Hacker News, sparking discussions about the benchmark's usefulness.
dylancastillo.co
11 min
7/22/2026
The gap between open weights LLMs and closed source LLMs
A prediction indicates that a new Frontier Open Source LLM will be released on December 3, 2026. The analysis compares the performance gap between open weights and closed source LLMs by examining historical benchmarks.
blog.doubleword.ai
2 min
6/26/2026
Anthropic: Introducing The Conceptual Reasoning Index
The Conceptual Reasoning Index introduces a suite of three benchmarks to evaluate AI capabilities in understanding situations, planning for the future, and developing risk mitigations. Access to the primary conceptual dataset, LMCA, is available upon request.
alignment.anthropic.com
6 min
8/13/2026
When AI Benchmarks Plateau: A Systematic Study of Benchmark Saturation
AI benchmarks are essential for assessing model performance and informing deployment choices. However, they often reach saturation, reducing their effectiveness in distinguishing between models and limiting their long-term utility.
arxiv.org
2 min
8/4/2026
Any text-to-SQL benchmark should address difficulties of real-world data stores
Text-to-SQL benchmarks must consider the complexities and challenges posed by real-world data stores. Effective evaluation should include factors like data variability, schema complexity, and query performance.
cacm.acm.org
1 min
7/22/2026
Kimi K3, and what we can still learn from the pelican benchmark
Moonshot AI has launched Kimi K3, their most capable model to date with 2.8 trillion parameters. It is currently accessible via their website and API, with an open weight release scheduled for July 27, 2026.
simonwillison.net
6 min
7/17/2026
GLM-5.2 is the new leading open weights model on Artificial Analysis
GLM-5.2 has become the leading open weights model on the Artificial Analysis Intelligence Index, scoring 51. It matches the size of GLM-5.1 with 744 billion total parameters and 40 billion active parameters, but surpasses it by 11 points in the Intelligence Index v4.1.
artificialanalysis.ai
3 min
6/17/2026
Models Are Getting Dumber on Purpose
Reasoning scores for AI models are increasing while per-token compute is decreasing. GLM-5.2 achieves 99.2% on AIME 2026 with 40 billion parameters, Qwen3.5 scores 91.3% with 17 billion parameters, and DeepSeek V4-Flash operates with 13 billion parameters, contrasting with GPT-4's rumored 280 billion parameters which struggled with AIME problems.
w4g1.dev
6 min
8/16/2026
When AI Benchmarks Plateau: A Systematic Study of Benchmark Saturation
AI benchmarks are essential for assessing model performance and informing deployment choices. However, they often reach saturation, reducing their effectiveness in distinguishing between models and limiting their long-term utility.
arxiv.org
2 min
8/4/2026
Are AI Labs Pelicanmaxxing?
Simon Willison has tested major LLM releases using the prompt “Generate an SVG of a pelican riding a bicycle,” creating an informal benchmark in AI. The results often receive significant engagement on platforms like Hacker News, sparking discussions about the benchmark's usefulness.
dylancastillo.co
11 min
7/22/2026
GLM-5.2 is the new leading open weights model on Artificial Analysis
GLM-5.2 has become the leading open weights model on the Artificial Analysis Intelligence Index, scoring 51. It matches the size of GLM-5.1 with 744 billion total parameters and 40 billion active parameters, but surpasses it by 11 points in the Intelligence Index v4.1.
artificialanalysis.ai
3 min
6/17/2026
Anthropic: Introducing The Conceptual Reasoning Index
The Conceptual Reasoning Index introduces a suite of three benchmarks to evaluate AI capabilities in understanding situations, planning for the future, and developing risk mitigations. Access to the primary conceptual dataset, LMCA, is available upon request.
alignment.anthropic.com
6 min
8/13/2026
What's the largest software project AI can complete on its own?
MirrorCode is a benchmark designed to evaluate AI models on long-horizon coding tasks by requiring them to reimplement entire programs end-to-end without access to the original source code. Solutions generated by AI must match the output of the original program to be considered successful.
epoch.ai
4 min
8/3/2026
Kimi K3, and what we can still learn from the pelican benchmark
Moonshot AI has launched Kimi K3, their most capable model to date with 2.8 trillion parameters. It is currently accessible via their website and API, with an open weight release scheduled for July 27, 2026.
simonwillison.net
6 min
7/17/2026
DeepSeek V4 Flash 0731
DeepSeek V4 Flash 0731 achieves scores of 89.0% on ARC-AGI-1 Semi-Private at a cost of $0.02 per task and 61.4% on ARC-AGI-2 Semi-Private at $0.04 per task. The model also records scores of 87.0% and 56.0% for the High variant, and 84.0% and 46.0% for the Low variant on the respective benchmarks.
arcprize.org
21 min
8/7/2026
Any text-to-SQL benchmark should address difficulties of real-world data stores
Text-to-SQL benchmarks must consider the complexities and challenges posed by real-world data stores. Effective evaluation should include factors like data variability, schema complexity, and query performance.
cacm.acm.org
1 min
7/22/2026
The gap between open weights LLMs and closed source LLMs
A prediction indicates that a new Frontier Open Source LLM will be released on December 3, 2026. The analysis compares the performance gap between open weights and closed source LLMs by examining historical benchmarks.
blog.doubleword.ai
2 min
6/26/2026