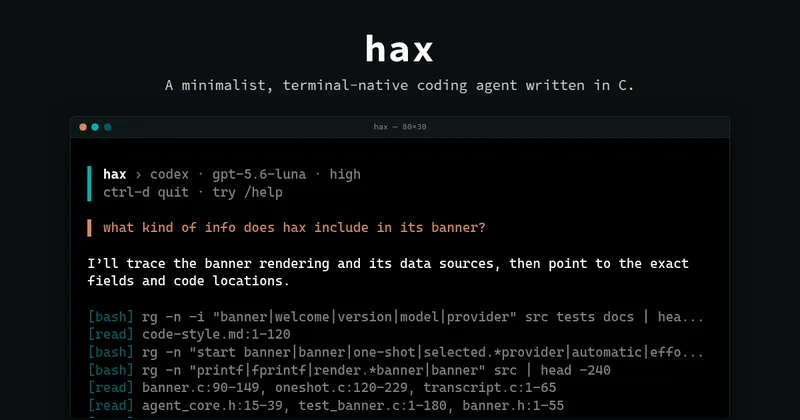
Hax – a minimalist, terminal-native coding agent written in C
hax is a lightweight terminal-native coding agent designed as a single native C binary with minimal dependencies, consuming only a few megabytes of memory. It automatically discovers local model capabilities without requiring custom provider configurations and streams Markdown and live tool output formatted for terminal display.
usehax.dev
2 min
8/12/2026
Muse Glimmer: 30B-parameter model optimized for always-on local agent workflows
Muse Glimmer is a 30-billion-parameter model developed by Meta Superintelligence Labs, optimized for local agent workflows. It can run on a Mac or PC with a single consumer GPU and is open-sourced under the Apache 2.0 license.
research.meta.ai
6 min
8/10/2026
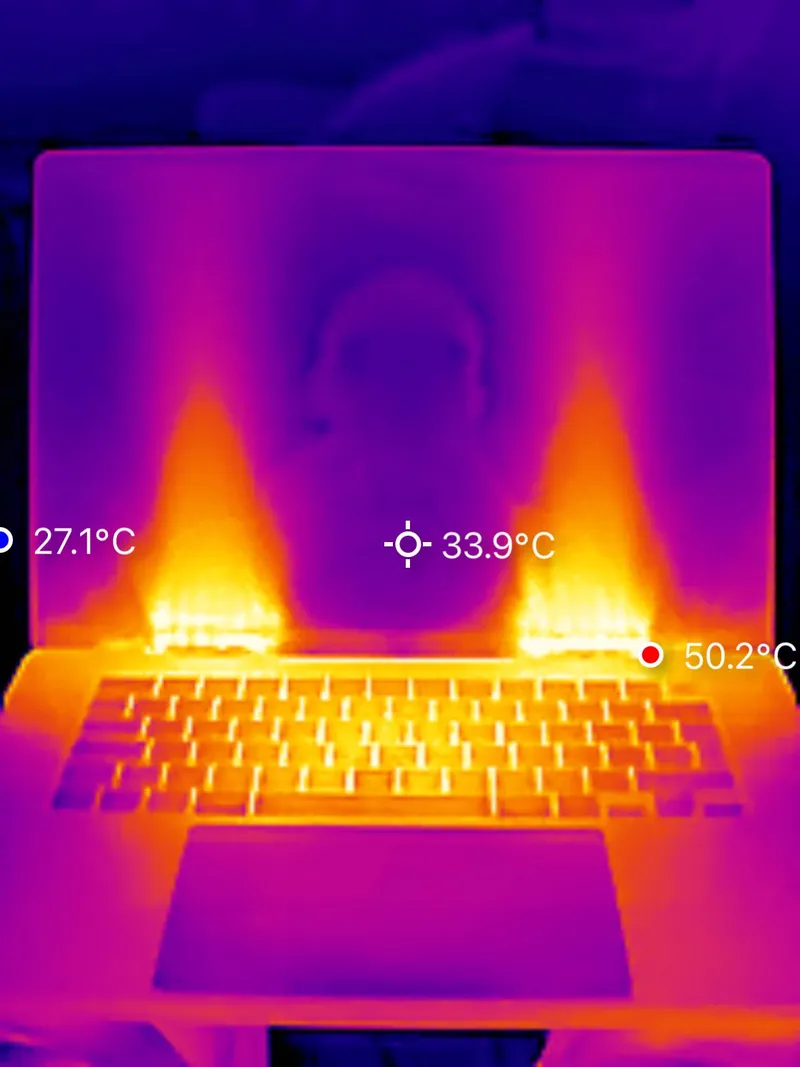
Qwen 3.6 27B is the sweet spot for local development
Qwen 3.6 27B is a dense local model recommended for its powerful performance in general intelligence tasks. It is slower than the mixture-of-experts variant Qwen 3.6 35B A3B but is considered more effective for local development.
quesma.com
6 min
6/29/2026
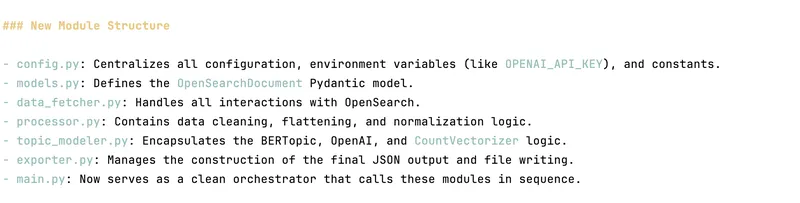
Running local models is good now
Local AI models have significantly improved in performance and usability. Various models such as Mistral 7B, Gemma 3, OpenAI OSS-20B, and Qwen 3 MOE have been successfully run on a 2022 M2 Mac with 64 GB RAM and 1TB storage using different setups including llama.cpp, llama-cpp-python, and LM Studio.
vickiboykis.com
6 min
6/16/2026
Running local models on an M4 with 24GB memory
Local models can be run on an M4 with 24GB of memory, allowing for basic tasks such as research and planning without an internet connection. This setup reduces dependence on major tech companies while providing a functional alternative to state-of-the-art models.
jola.dev
8 min
5/10/2026
Hax – a minimalist, terminal-native coding agent written in C
hax is a lightweight terminal-native coding agent designed as a single native C binary with minimal dependencies, consuming only a few megabytes of memory. It automatically discovers local model capabilities without requiring custom provider configurations and streams Markdown and live tool output formatted for terminal display.
usehax.dev
2 min
8/12/2026
Qwen 3.6 27B is the sweet spot for local development
Qwen 3.6 27B is a dense local model recommended for its powerful performance in general intelligence tasks. It is slower than the mixture-of-experts variant Qwen 3.6 35B A3B but is considered more effective for local development.
quesma.com
6 min
6/29/2026
Running local models on an M4 with 24GB memory
Local models can be run on an M4 with 24GB of memory, allowing for basic tasks such as research and planning without an internet connection. This setup reduces dependence on major tech companies while providing a functional alternative to state-of-the-art models.
jola.dev
8 min
5/10/2026
Muse Glimmer: 30B-parameter model optimized for always-on local agent workflows
Muse Glimmer is a 30-billion-parameter model developed by Meta Superintelligence Labs, optimized for local agent workflows. It can run on a Mac or PC with a single consumer GPU and is open-sourced under the Apache 2.0 license.
research.meta.ai
6 min
8/10/2026
Running local models is good now
Local AI models have significantly improved in performance and usability. Various models such as Mistral 7B, Gemma 3, OpenAI OSS-20B, and Qwen 3 MOE have been successfully run on a 2022 M2 Mac with 64 GB RAM and 1TB storage using different setups including llama.cpp, llama-cpp-python, and LM Studio.
vickiboykis.com
6 min
6/16/2026
Hax – a minimalist, terminal-native coding agent written in C
hax is a lightweight terminal-native coding agent designed as a single native C binary with minimal dependencies, consuming only a few megabytes of memory. It automatically discovers local model capabilities without requiring custom provider configurations and streams Markdown and live tool output formatted for terminal display.
usehax.dev
2 min
8/12/2026
Running local models is good now
Local AI models have significantly improved in performance and usability. Various models such as Mistral 7B, Gemma 3, OpenAI OSS-20B, and Qwen 3 MOE have been successfully run on a 2022 M2 Mac with 64 GB RAM and 1TB storage using different setups including llama.cpp, llama-cpp-python, and LM Studio.
vickiboykis.com
6 min
6/16/2026
Muse Glimmer: 30B-parameter model optimized for always-on local agent workflows
Muse Glimmer is a 30-billion-parameter model developed by Meta Superintelligence Labs, optimized for local agent workflows. It can run on a Mac or PC with a single consumer GPU and is open-sourced under the Apache 2.0 license.
research.meta.ai
6 min
8/10/2026
Running local models on an M4 with 24GB memory
Local models can be run on an M4 with 24GB of memory, allowing for basic tasks such as research and planning without an internet connection. This setup reduces dependence on major tech companies while providing a functional alternative to state-of-the-art models.
jola.dev
8 min
5/10/2026
Qwen 3.6 27B is the sweet spot for local development
Qwen 3.6 27B is a dense local model recommended for its powerful performance in general intelligence tasks. It is slower than the mixture-of-experts variant Qwen 3.6 35B A3B but is considered more effective for local development.
quesma.com
6 min
6/29/2026
No more articles to load