AirLLM 70B inference with single 4GB GPU
github.com
August 3, 2026
7 min read
🔥🔥🔥🔥🔥
59/100
Summary
AirLLM enables 70B large language models to run on a single 4GB GPU without quantization, distillation, or pruning. Sparse MoE models allow for running larger models, such as the 405B Llama 3.1 on 8GB and the 2.8T Kimi K3 on under 4GB, by streaming one expert at a time.
Key Takeaways
- AirLLM enables 70B large language models to run on a single 4GB GPU without quantization, distillation, or pruning.
- The largest open-source model, Kimi K3 (2.8T), can operate on a single card with only 3.72GB of VRAM.
- AirLLM supports various models including Llama 3.1, DeepSeek-V3, and Qwen3, with capabilities for both GPU and CPU inference.
- Model compression techniques in AirLLM can achieve up to a 3x speed improvement during inference with minimal accuracy loss.
Coverage & discussions
Hacker News · github.com
Community discussions
Community Sentiment
Positives
- Running a 1TB model with just 1GB RAM is a game changer for those with limited hardware — it’s a step towards making advanced AI accessible to more users.
- The community is excited about the potential for these projects to enable real-time applications, even if they come with some quirks.
- Innovative solutions like this could lead to a rethinking of model architecture, pushing for better performance with less resource consumption.
Concerns
- Skeptics point out that many of these projects feel 'vibe coded' and lack long-term viability, raising doubts about their utility.
- The documentation is a mess — users are frustrated by the lack of clear guidance on how to effectively use the models.
- There’s a concern that while this tech is intriguing, it may not be functionally useful for real-world applications, especially for those with mid-range setups.
Related Articles
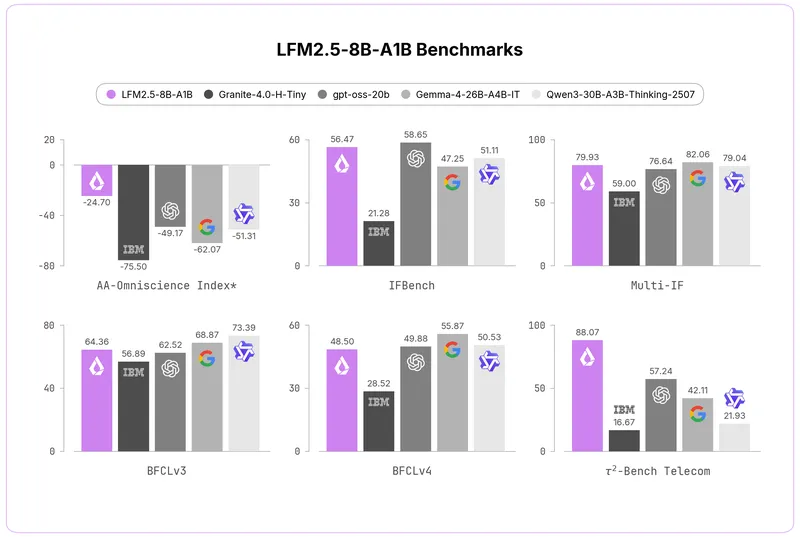
Liquid AI reveals 8B-A1B MoE trained on 38T
May 29, 2026
Right-sizes LLM models to your system's RAM, CPU, and GPU
Mar 1, 2026
Running Gemma 4 locally with LM Studio's new headless CLI and Claude Code
Apr 5, 2026
TurboQuant KV Compression and SSD Expert Streaming for M5 Pro and IOS
Apr 1, 2026

A 10 year old Xeon is all you need
Jun 1, 2026