Report · artificialanalysis.ai
GLM 5.2 Performance Benchmarks
artificialanalysis.ai
Source published June 17, 2026
Summary: 1 min read
55/100
Summary
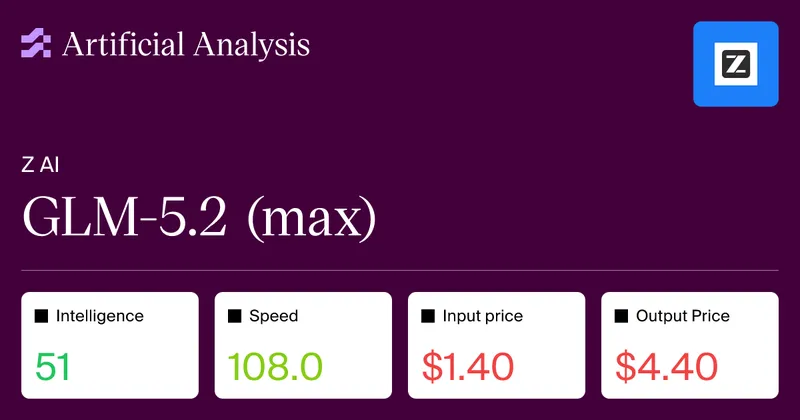
GLM-5.2 (max) is a leading model in intelligence with a score of 51 on the Artificial Analysis Intelligence Index. It offers a 1 million token context window, supports text input and output, is faster than average, but is considered expensive compared to other open weight models of similar size.
Key Takeaways
- GLM-5.2 (max) scores 51 on the Artificial Analysis Intelligence Index, significantly above the average score of 24 for comparable models.
- The pricing for GLM-5.2 (max) is $1.40 per 1M input tokens and $4.40 per 1M output tokens, making it more expensive than the average prices of $0.42 and $1.25, respectively.
- GLM-5.2 (max) generates output at a speed of 108 tokens per second, which is faster than the average speed of 60 tokens per second for similar models.
- The model has a context window of 1 million tokens, allowing for extensive text input and output capabilities.
Coverage & discussions
Hacker News · artificialanalysis.ai
Community discussions
Community Sentiment
Positives
- GLM 5.2 excels in the 'AA-Omniscience Non-Hallucination Rate', outperforming models like DeepSeek and GPT 5.5, which highlights its reliability in uncertain scenarios.
- The model's performance improvements, being 30% faster than its predecessor, indicate significant advancements in efficiency that could enhance user experience.
- Local models are becoming increasingly useful, suggesting a shift towards more accessible AI solutions that could democratize technology for a wider audience.
Concerns
- Concerns arise over the validity of the 'AA-Omniscience Non-Hallucination Rate' benchmark, as it seems to favor models that avoid complex reasoning, potentially misleading users about true performance.
- Skepticism about the benchmarks is prevalent, especially when models like Muse Spark are rated higher than GPT-5.5, raising doubts about the accuracy of the evaluations.
- The high costs associated with deploying these models on local hardware may hinder accessibility, limiting their practical use for many developers and organizations.
Related Articles
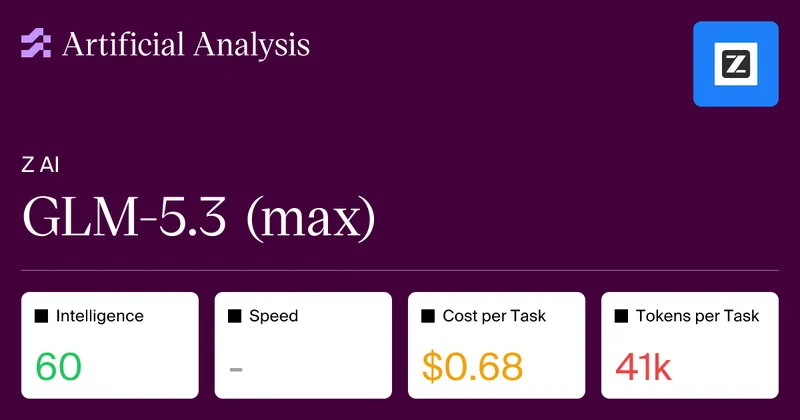
GLM-5.3 Artificial Analysis Benchmarks
Aug 18, 2026
GLM-5.3-Flash Intelligence, Performance and Price Analysis
Aug 26, 2026
GLM-5.2 is the new leading open weights model on Artificial Analysis
Jun 17, 2026
DeepSeek V4.1 Flash 1017 (Max)
Oct 19, 2026
Opus 5 is currently #1 on Artificial Analysis Intelligence Leaderboard
Jul 24, 2026