LoRA Speedrun – a public wall-clock leaderboard for fine-tuning techniques
github.com
July 20, 2026
6 min read
54/100
Summary
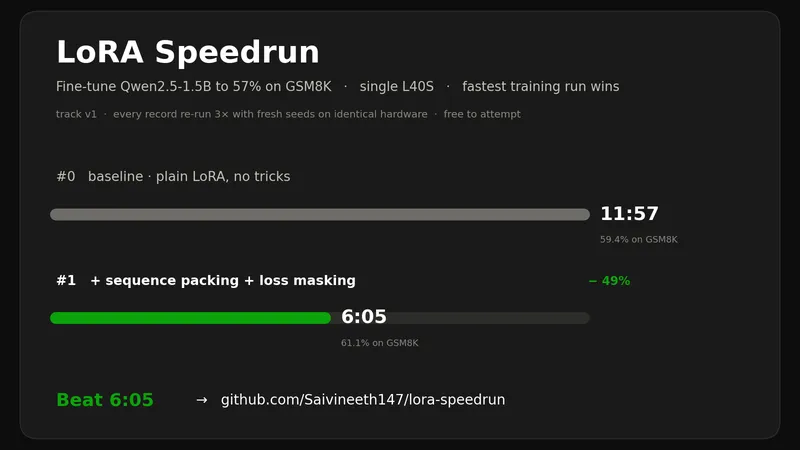
GitHub repository Saivineeth147/lora-speedrun enables speedrunning LoRA fine-tuning for the Qwen2.5-1.5B model on a single L40S GPU, aiming for ≥ 57% accuracy on GSM8K. The project features a frozen task and hardware setup, with a public leaderboard that requires independent verification of timing runs conducted on Modal's sandbox using free compute credits.
Key Takeaways
- The current record for LoRA fine-tuning Qwen2.5-1.5B on GSM8K is 6 minutes and 5 seconds, achieved by @Saivineeth147 using sequence packing and completion-only loss masking with 2 epochs.
- The leaderboard for LoRA fine-tuning allows anyone to compete and verify records using a Modal L40S sandbox, with official timing runs covering full attempts.
- The project aims to create a standardized environment for comparing different fine-tuning techniques by using frozen tasks and identical hardware across two distinct tracks.
- LoRA/QLoRA techniques are prevalent in real-world fine-tuning, and this repository provides a competitive arena for these methods to be tested against each other in a public format.
Related Articles
Auto-research with codex: How I achieved a 232x Faster Kernel
Aug 15, 2026
$500 GPU outperforms Claude Sonnet on coding benchmarks
Mar 26, 2026
LLM Neuroanatomy II: Modern LLM Hacking and Hints of a Universal Language?
Mar 24, 2026
We got 207 tok/s with Qwen3.5-27B on an RTX 3090
Apr 20, 2026
Local Qwen isn't a worse Opus, it's a different tool
Jun 18, 2026