Real-time LLM Inference on Standard GPUs: 3k tokens/s per request
blog.kog.ai
May 29, 2026
18 min read
58/100
Summary
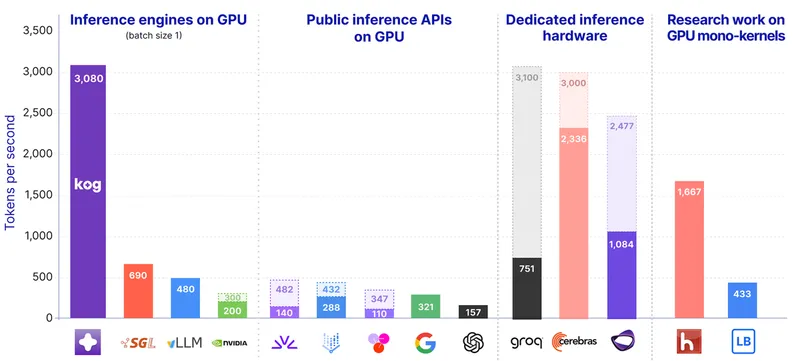
Kog AI has launched a tech preview of the Kog Inference Engine (KIE), achieving 3,000 output tokens per second on 8× AMD MI300X GPUs and 2,100 on 8× NVIDIA H200 GPUs using FP16 without speculative decoding. The preview currently supports a 2B model, with plans to add support for large third-party MoE models at similar speeds.
Key Takeaways
- Kog AI launched the Kog Inference Engine (KIE), achieving 3,000 output tokens per second on 8× AMD MI300X GPUs and 2,100 on 8× NVIDIA H200 GPUs.
- The primary bottleneck for fast token generation on GPUs is memory bandwidth, which limits decoding speed during autoregressive decoding.
- Optimizing single-request latency is crucial for AI agents, as it significantly impacts user experience and productivity in iterative workflows.
- The KIE tech preview demonstrates that standard datacenter GPUs can achieve speeds comparable to dedicated inference hardware by optimizing the software stack.
Coverage & discussions
Hacker News · blog.kog.ai
Community discussions
Community Sentiment
Positives
- Achieving 3k tokens per second on standard GPUs opens up exciting possibilities for real-time applications, making advanced AI more accessible.
- The demo showcases the potential for rapid inference, hinting at future advancements in AI capabilities and user experiences.
- The focus on standard GPUs rather than custom chips suggests a push towards democratizing access to powerful AI tools.
Concerns
- The comparison of a 2B model against much larger frontier models raises concerns about the fairness and relevance of the benchmarks presented.
- Some users feel that the term 'standard GPUs' is misleading, as it primarily refers to high-end data center GPUs rather than consumer-grade hardware.
- The performance of the small model in the demo has been criticized for lacking depth, indicating limitations in its practical applications.
Related Articles
Smaller, faster, safer: running Kimi and GLM at scale
Aug 3, 2026

A 10 year old Xeon is all you need
Jun 1, 2026
OpenAI Jalapeño: Better than Nvidia Blackwell
Aug 25, 2026
Self-hosting Kimi K3: 20% more hardware cost, 20% better task resolution
Jul 29, 2026
Performance per dollar is getting faster and cheaper
Jul 3, 2026