Running a One Trillion-Parameter LLM Locally on AMD Ryzen AI Max+ Cluster
amd.com
March 1, 2026
14 min read
🔥🔥🔥🔥🔥
47/100
Summary
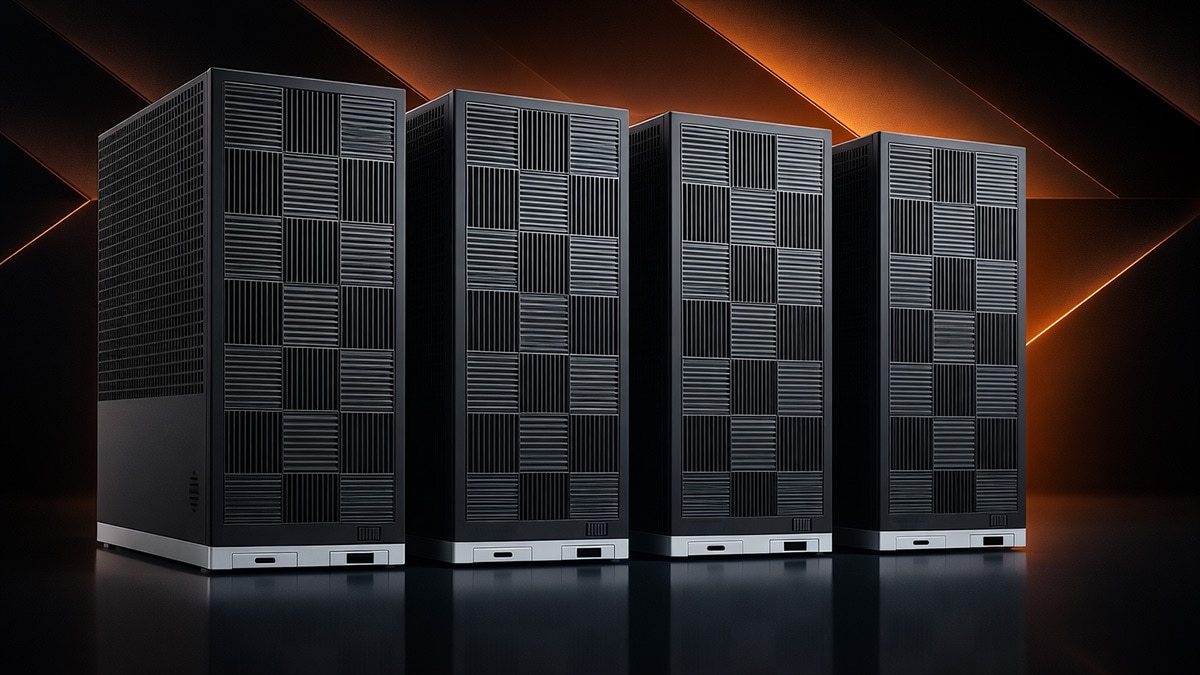
A small-scale distributed inference cluster can be built using AMD’s Ryzen™ AI Max+ AI PC platform to run a one trillion-parameter Large Language Model. A four-node cluster of Framework Desktop systems demonstrates the local inference of the Kimi K2.5 open-source model.
Key Takeaways
- A one trillion-parameter Large Language Model, Kimi K2.5, can be run locally on a four-node cluster of AMD Ryzen AI Max+ systems using llama.cpp RPC.
- The maximum VRAM allocation for each node in the cluster can be increased to 120GB, allowing a total of 480GB across four nodes.
- The Lemonade SDK provides pre-built binaries for easier setup of llama.cpp with AMD ROCm acceleration for Ryzen AI Max+ systems.
- Kimi K2.5 is designed for software engineering tasks and can process multimodal inputs, including visual and video data.
Coverage & discussions
Hacker News · amd.com
Community discussions
Community Sentiment
Positives
- Running a one trillion-parameter LLM locally showcases significant advancements in AI capabilities, making high-performance models more accessible to enthusiasts.
- The ability to run such a large model on consumer hardware indicates a promising trend towards democratizing AI technology.
Concerns
- Performance metrics reveal that the system struggles with low throughput (<10 tps) and high latency, making it impractical for real-time applications.
- The reported time-to-first-token of over a minute for an 8192 token prompt highlights severe inefficiencies compared to leading models like ChatGPT.
- The hardware's limitations, such as non-upgradable components and slow networking options, raise concerns about its long-term viability and usability.
Related Articles
Smaller, faster, safer: running Kimi and GLM at scale
Aug 3, 2026

A 10 year old Xeon is all you need
Jun 1, 2026
AirLLM 70B inference with single 4GB GPU
Aug 3, 2026
Performance per dollar is getting faster and cheaper
Jul 3, 2026
Running Gemma 4 locally with LM Studio's new headless CLI and Claude Code
Apr 5, 2026