How the Claude Code team does code review
Anthropic’s Claude Code team has shifted most code review work to automated systems as AI agents generate a growing share of its software. Claude writes about 90% of Claude Code’s code, while merged pull requests more than doubled from June to September and the share requiring reverts fell by more than 40%, according to the team. Anthropic’s monorepo rose from roughly 2,500 changes per day in May to more than 30,000 in September. Every Claude Code pull request receives automated bug and security reviews before human review. Agents verify proposed findings, discard style-only or insufficiently supported comments, and rank remaining issues by severity. Automated checks include linting, type checks, builds, cross-platform tests, and merge-queue validation against the main branch. Changes are classified as low, medium, or high risk: low-risk changes can merge without human approval once automated checks pass, medium-risk changes need one human, and high-risk changes need two. Only trusted authors can use lighter review paths, and agent approvals never substitute for required human approvals. The team uses feature flags, staged latest-channel releases, on-call rotations, reverts, and incident reviews to limit damage from missed defects. It also evaluates reviewers daily against past incident-causing pull requests and tracks false-positive noise and review rounds. One pull request underwent more than 50 automated review-and-fix rounds overnight, prompting the team to measure rounds-to-pass and limit repeated review.
claude.dev
13 min
6h ago
Llama.cpp on a jailbroken PS5: run any GGUF model natively on the console
PS5LM is a homebrew application that runs GGUF language and decision models locally on jailbroken PlayStation 5 consoles using llama.cpp’s Vulkan backend and the console’s RDNA 2 GPU. It turns the PS5 into a private network model server without requiring a PC, cloud service or account while running. Devices on the local network can access OpenAI-compatible /v1/chat/completions and Anthropic-compatible /v1/messages endpoints at the console’s port 8081; Claude Code can use the Anthropic-compatible API. The application assigns up to 11.4 GB of shared PS5 memory to a model and its context, selects a context length and cache that fit available memory, and can download supported GGUF files from Hugging Face. Listed PS5 Slim performance includes 207 tokens per second for Qwen 3.5 0.8B Q4_K_M, 55 tokens per second for Qwen 3.5 9B Q4_K_M, and about 20 tokens per second with a 64,000-token context for Qwen 3.8 27B UD-Q2_K_XL. PS5LM also supports GGUF decision models with llama.cpp decision metadata, including d1, Clef and OpenJev models. These models serve TypeSafe’s /v1/systemone API for typed choices, scores and yes-or-no responses about text and images. PS5LM requires a PS5 on firmware 7.00 through 13.60 with a jailbreak and specified homebrew payloads, including kstuff-lite, etaHEN and ShadowMountPlus.
github.com
5 min
1h ago
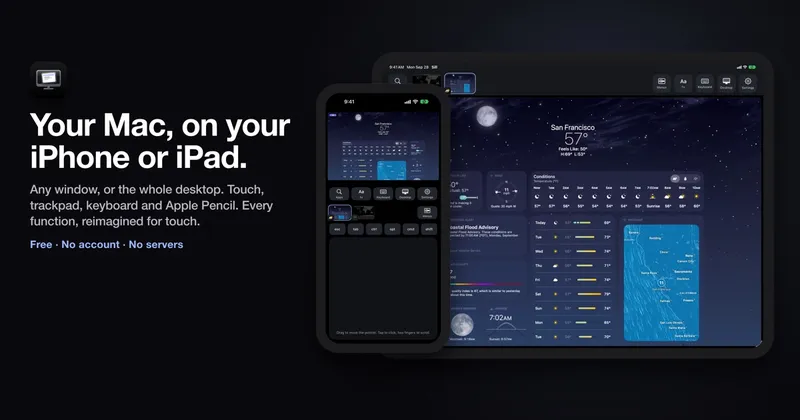
Any window from your Mac, on your iPhone and iPad
Sill is a free, open-source Mac, iPhone, and iPad application that streams either one Mac window or the entire desktop to a paired mobile device and returns touch, keyboard, trackpad, mouse, scrolling, and Apple Pencil input to the Mac. Sill for Mac captures content with ScreenCaptureKit, encodes it as HEVC using VideoToolbox, and sends it directly to the iPhone or iPad app over TLS 1.3. It drops delayed frames rather than queueing them to keep the displayed image current. The software works on Apple-silicon Macs running macOS 14 or later and iPhones or iPads running iOS or iPadOS 17 or later. Devices can connect over a shared local network, USB, peer-to-peer Wi-Fi through Direct Wireless Connection, or a user-managed VPN or forwarded router port with Remote Access enabled. Each device is paired once using a 12-digit code or USB, and subsequent connections are pinned to the paired keys. Sill has no account, intermediary server, ads, tracking, or subscription. It supports bidirectional text clipboard sharing up to 256 KB, but does not stream Mac audio and shows only one window or the desktop at a time. The Mac app requires Screen Recording and Accessibility permissions; the latter lets it generate mouse and keyboard events and resize streamed windows. Sill is available as a notarized Mac download, through Homebrew, and as a free iPhone and iPad App Store app under the Apache 2.0 license.
github.com
9 min
19h ago
BeBox is a Haiku application that emulates Be Inc.'s BeBox
BeBox is a Haiku application that emulates Be Inc.’s dual-processor BeBox systems and earlier Hobbit-based prototypes. It runs the 66 MHz dual-PowerPC 603 BeBox and the 133 MHz dual-PowerPC 603e model from original boot ROMs, supporting PowerPC BeOS releases from Developer Release 6 through R5.0.3. The emulator includes PowerPC processors, the MPC105 bridge, writable flash ROM, NVRAM, SCSI, IDE, floppy storage, video, sound, serial ports, game ports and NE2000-compatible Ethernet. It displays the BeBox’s two columns of front-panel LEDs and can run both emulated processors on separate host CPU cores. The Hobbit mode emulates two 25 MHz AT&T 92010 processors and hardware used in Be prototypes from 1993-94. Because no Hobbit boot ROM survives, BeBox directly loads the prototype system kernel from a floppy or SCSI disk image. Hobbit emulation includes SCSI, floppy DMA, serial ports, keyboard, mouse and Trident VGA graphics, but not its DSPs, sound, Ethernet, joystick or parallel hardware. BeBox supports raw and QCOW2 disk images, overlays, Haiku shared folders mounted by BeOS as BFS disks, NAT-based networking and port forwarding. Original BeBox ROMs, BeOS media and prototype disk images are required separately and are not included.
github.com
13 min
13h ago
Muse Spark Open
Meta has released the weights for Muse Spark Open, an open-weight, natively multimodal AI model designed for coding, agentic workflows, complex software engineering, and multi-step reasoning. The model has 816 billion total parameters, with 42 billion active parameters, and supports a context window of up to 1 million tokens. Meta calls it the most capable US open-weight model to date. Muse Spark Open can run locally on two Apple M5 Ultra Mac Studio systems using Apple’s MLX framework. Each M5 Ultra can provide up to 512 GB of unified memory and 1.2 TB/s of memory bandwidth, allowing the two systems to hold the full model. Meta tested on-device workflows with Muse Code, including making bug fixes and adding features to the Ice Cubes Mastodon client, as well as reviewing and vertically cropping video in DaVinci Resolve. The weights are available through Amazon SageMaker AI, Google Cloud Model Garden, Hugging Face, and Microsoft Foundry Models, while hosted inference is offered through Baseten, Fireworks AI, Groq, Modal, Nebius, OpenRouter, and Together AI. The model supports engines including SGLang, vLLM, TensorRT-LLM, Transformers, MLX, llama.cpp, and Unsloth. Meta says its SGLang kernels deliver 1.03-3.95 times kernel-level speedups on NVIDIA and AMD GPUs. The model is released under the Muse Model License with limited commercial terms.
research.meta.ai
3 min
1d ago
CEO fired developers to make room for AI. Developers create open source AI CEO
Open Executive is an Apache 2.0-licensed, open-source virtual executive team built by SenteLabsAI. It presents users with one executive persona while an orchestrator routes requests to eight specialists covering strategy, finance, people, legal basics and compliance, operations, marketing, product, and board communications. The system uses Anthropic’s Claude API by default, with claude-sonnet-4-6 for the executive and most specialists and claude-opus-4-7 with extended thinking for strategy, finance, legal, and board work. It can also use OpenRouter or OpenAI-compatible local model servers such as Ollama, LM Studio, vLLM, and llama.cpp. Each specialist retrieves built-in business knowledge and uploaded company documents from separate ChromaDB collections. A background claude-haiku-4-5 process extracts decisions, initiatives, and advice into SQLite after responses, allowing later sessions to receive prior-decision context. A built-in scheduler can surface follow-ups but requires the FastAPI service to run as a single instance to avoid duplicate actions. The stack includes Python 3.11, FastAPI, Next.js 15, Tailwind, ChromaDB, and SQLite. Users can access it through a web interface, CLI, Slack, email, Telegram, Google Chat, or Discord. Local setup requires Python 3.11+, Node 22+, and an API provider configuration; the first start downloads an approximately 90 MB embedding model.
github.com
13 min
8/27/2026
Serve Markdown to AI Agents with Accept Headers
AcceptMarkdown.com promotes serving Markdown versions of web pages to AI agents through HTTP content negotiation. Clients can request a Markdown representation with the `Accept: text/markdown` header, allowing them to receive page content without navigation, scripts, styles, layout wrappers, advertisements, related-content sections, or modal overlays. The site says Markdown responses use a fraction of the bytes of full pages and can leave AI agents’ context windows focused on prose rather than DOM markup. It also says cleaner text can improve signal-to-noise for retrieval-augmented generation pipelines and that smaller responses can reduce fetching, parsing, and context-loading work before a model begins generating output. Its URL checker sends an edge request with `Accept: text/markdown` and reports what the origin returns. The checker evaluates whether a URL serves Markdown for that request, sets `Vary: Accept`, rejects unsupported content types with HTTP 406, and honors HTTP `q` quality values in Accept headers.
acceptmarkdown.com
1 min
8/26/2026
WebMCP: Teaching Your Website to Talk to AI Agents
WebMCP is a proposed web standard that lets websites expose structured JavaScript tools for AI agents to discover and invoke, replacing brittle screen-scraping of buttons, HTML and visual layouts. A page can register actions such as booking a table, checking out, filtering results or adding a to-do item, with JSON Schema definitions for their inputs and outputs. The tools execute within the user’s already open and authenticated browser tab, using site functions that already exist rather than requiring a separate automation bot. Google and Microsoft are developing WebMCP in the W3C Web Machine Learning Community Group. It remains a Community Group draft rather than a finished W3C standard or standards-track specification. Chrome offers it behind a testing flag, and the current API uses document.modelContext; earlier drafts used navigator.modelContext. ChatGPT supports WebMCP-enabled pages, according to an OpenAI Developers post dated August 26, 2026. The design includes same-origin tool registration through a tools Permissions Policy, visible execution in an open browsing context, optional confirmation for sensitive actions, and annotations including readOnlyHint and untrustedContentHint. These protections do not eliminate security risks, and the security model is still under development. WebMCP could enable agent-operated commerce, bookings, scheduling and support flows when sites explicitly expose the necessary tools and users approve consequential actions.
sreenathmenon.com
12 min
8/26/2026
RAG Is Simpler Than You Think
Retrieval-augmented generation systems can begin with BM25 or other full-text search rather than embeddings and vector databases, particularly for keyword-heavy queries, exact identifiers, proprietary terminology, low query volumes, and frequently changing content. The source recommends measuring a baseline for two to four weeks, then adding complexity only when user feedback and evaluation data show that simpler retrieval fails. Full-text search avoids embedding API costs, document chunking, re-indexing, and model-deprecation risks; it can return results in under 10 milliseconds, according to the source. LLM-based query rewriting can convert conversational requests into keyword searches, add synonyms, preserve internal product names, and decompose complex questions at an estimated cost of about $0.001 per query using GPT-4o-mini. Hybrid retrieval uses BM25 to select 50 to 100 candidates and embeddings to rerank the top results, trading stronger semantic matching for roughly 200–500 milliseconds of added latency when documents are embedded on demand. On-the-fly embedding suits high-churn data, while hot/cold tiers pre-embed commonly accessed documents and process less-used material dynamically. Full pre-embedding is presented as appropriate for stable corpora, broad access patterns, more than 10,000 daily queries, and sub-50-millisecond latency requirements. The source estimates that 60% of systems can stop at full-text search plus query rewriting.
lighthousenewsletter.com
13 min
8/26/2026
Queryable Executables
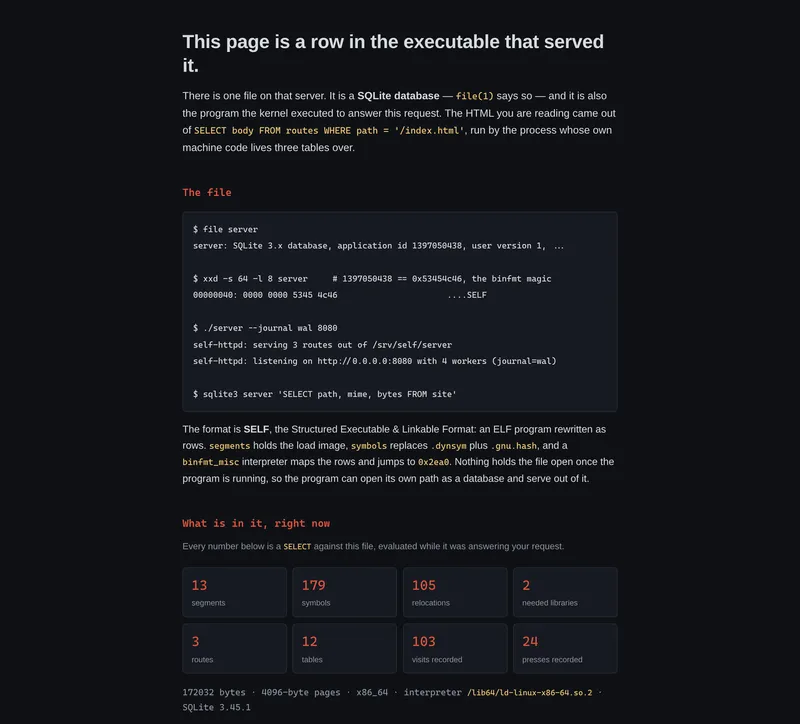
SELF is an executable format that stores a program as a SQLite database, with executable segments represented as database rows. A Linux binfmt_misc interpreter maps those rows and transfers control to the program entry point, allowing executable contents and related metadata to be queried with SQL. The format can also let a running program open its own SQLite file through argv[0] and persist state in that same file; /proc/self/exe does not currently provide the original file in this setup. The self-httpd proof of concept packages a web server, website routes, visitor logs and button-press records into one SQLite database file. Its routes, visits and presses tables store page content and runtime data, while the server can query its own segments, symbols and relocations. A POST request to its /api/press endpoint inserts a button press into the executable’s database, and the live demonstration is hosted at selfdb.exe.xyz. SQLite transactions allow site content in the running file to be updated or rolled back without restarting the server. SQLite tools such as sqldiff can compare code, route and metadata changes between versions, and FTS5 can index pages stored in the executable. Deployments can copy a single file, while SQL INSERT ... SELECT statements can migrate tables such as visitor logs and button presses from an old file to a new build before it is swapped in.
fzakaria.com
7 min
8/26/2026
How the Claude Code team does code review
Anthropic’s Claude Code team has shifted most code review work to automated systems as AI agents generate a growing share of its software. Claude writes about 90% of Claude Code’s code, while merged pull requests more than doubled from June to September and the share requiring reverts fell by more than 40%, according to the team. Anthropic’s monorepo rose from roughly 2,500 changes per day in May to more than 30,000 in September. Every Claude Code pull request receives automated bug and security reviews before human review. Agents verify proposed findings, discard style-only or insufficiently supported comments, and rank remaining issues by severity. Automated checks include linting, type checks, builds, cross-platform tests, and merge-queue validation against the main branch. Changes are classified as low, medium, or high risk: low-risk changes can merge without human approval once automated checks pass, medium-risk changes need one human, and high-risk changes need two. Only trusted authors can use lighter review paths, and agent approvals never substitute for required human approvals. The team uses feature flags, staged latest-channel releases, on-call rotations, reverts, and incident reviews to limit damage from missed defects. It also evaluates reviewers daily against past incident-causing pull requests and tracks false-positive noise and review rounds. One pull request underwent more than 50 automated review-and-fix rounds overnight, prompting the team to measure rounds-to-pass and limit repeated review.
claude.dev
13 min
6h ago
Any window from your Mac, on your iPhone and iPad
Sill is a free, open-source Mac, iPhone, and iPad application that streams either one Mac window or the entire desktop to a paired mobile device and returns touch, keyboard, trackpad, mouse, scrolling, and Apple Pencil input to the Mac. Sill for Mac captures content with ScreenCaptureKit, encodes it as HEVC using VideoToolbox, and sends it directly to the iPhone or iPad app over TLS 1.3. It drops delayed frames rather than queueing them to keep the displayed image current. The software works on Apple-silicon Macs running macOS 14 or later and iPhones or iPads running iOS or iPadOS 17 or later. Devices can connect over a shared local network, USB, peer-to-peer Wi-Fi through Direct Wireless Connection, or a user-managed VPN or forwarded router port with Remote Access enabled. Each device is paired once using a 12-digit code or USB, and subsequent connections are pinned to the paired keys. Sill has no account, intermediary server, ads, tracking, or subscription. It supports bidirectional text clipboard sharing up to 256 KB, but does not stream Mac audio and shows only one window or the desktop at a time. The Mac app requires Screen Recording and Accessibility permissions; the latter lets it generate mouse and keyboard events and resize streamed windows. Sill is available as a notarized Mac download, through Homebrew, and as a free iPhone and iPad App Store app under the Apache 2.0 license.
github.com
9 min
19h ago
Muse Spark Open
Meta has released the weights for Muse Spark Open, an open-weight, natively multimodal AI model designed for coding, agentic workflows, complex software engineering, and multi-step reasoning. The model has 816 billion total parameters, with 42 billion active parameters, and supports a context window of up to 1 million tokens. Meta calls it the most capable US open-weight model to date. Muse Spark Open can run locally on two Apple M5 Ultra Mac Studio systems using Apple’s MLX framework. Each M5 Ultra can provide up to 512 GB of unified memory and 1.2 TB/s of memory bandwidth, allowing the two systems to hold the full model. Meta tested on-device workflows with Muse Code, including making bug fixes and adding features to the Ice Cubes Mastodon client, as well as reviewing and vertically cropping video in DaVinci Resolve. The weights are available through Amazon SageMaker AI, Google Cloud Model Garden, Hugging Face, and Microsoft Foundry Models, while hosted inference is offered through Baseten, Fireworks AI, Groq, Modal, Nebius, OpenRouter, and Together AI. The model supports engines including SGLang, vLLM, TensorRT-LLM, Transformers, MLX, llama.cpp, and Unsloth. Meta says its SGLang kernels deliver 1.03-3.95 times kernel-level speedups on NVIDIA and AMD GPUs. The model is released under the Muse Model License with limited commercial terms.
research.meta.ai
3 min
1d ago
Serve Markdown to AI Agents with Accept Headers
AcceptMarkdown.com promotes serving Markdown versions of web pages to AI agents through HTTP content negotiation. Clients can request a Markdown representation with the `Accept: text/markdown` header, allowing them to receive page content without navigation, scripts, styles, layout wrappers, advertisements, related-content sections, or modal overlays. The site says Markdown responses use a fraction of the bytes of full pages and can leave AI agents’ context windows focused on prose rather than DOM markup. It also says cleaner text can improve signal-to-noise for retrieval-augmented generation pipelines and that smaller responses can reduce fetching, parsing, and context-loading work before a model begins generating output. Its URL checker sends an edge request with `Accept: text/markdown` and reports what the origin returns. The checker evaluates whether a URL serves Markdown for that request, sets `Vary: Accept`, rejects unsupported content types with HTTP 406, and honors HTTP `q` quality values in Accept headers.
acceptmarkdown.com
1 min
8/26/2026
RAG Is Simpler Than You Think
Retrieval-augmented generation systems can begin with BM25 or other full-text search rather than embeddings and vector databases, particularly for keyword-heavy queries, exact identifiers, proprietary terminology, low query volumes, and frequently changing content. The source recommends measuring a baseline for two to four weeks, then adding complexity only when user feedback and evaluation data show that simpler retrieval fails. Full-text search avoids embedding API costs, document chunking, re-indexing, and model-deprecation risks; it can return results in under 10 milliseconds, according to the source. LLM-based query rewriting can convert conversational requests into keyword searches, add synonyms, preserve internal product names, and decompose complex questions at an estimated cost of about $0.001 per query using GPT-4o-mini. Hybrid retrieval uses BM25 to select 50 to 100 candidates and embeddings to rerank the top results, trading stronger semantic matching for roughly 200–500 milliseconds of added latency when documents are embedded on demand. On-the-fly embedding suits high-churn data, while hot/cold tiers pre-embed commonly accessed documents and process less-used material dynamically. Full pre-embedding is presented as appropriate for stable corpora, broad access patterns, more than 10,000 daily queries, and sub-50-millisecond latency requirements. The source estimates that 60% of systems can stop at full-text search plus query rewriting.
lighthousenewsletter.com
13 min
8/26/2026
Llama.cpp on a jailbroken PS5: run any GGUF model natively on the console
PS5LM is a homebrew application that runs GGUF language and decision models locally on jailbroken PlayStation 5 consoles using llama.cpp’s Vulkan backend and the console’s RDNA 2 GPU. It turns the PS5 into a private network model server without requiring a PC, cloud service or account while running. Devices on the local network can access OpenAI-compatible /v1/chat/completions and Anthropic-compatible /v1/messages endpoints at the console’s port 8081; Claude Code can use the Anthropic-compatible API. The application assigns up to 11.4 GB of shared PS5 memory to a model and its context, selects a context length and cache that fit available memory, and can download supported GGUF files from Hugging Face. Listed PS5 Slim performance includes 207 tokens per second for Qwen 3.5 0.8B Q4_K_M, 55 tokens per second for Qwen 3.5 9B Q4_K_M, and about 20 tokens per second with a 64,000-token context for Qwen 3.8 27B UD-Q2_K_XL. PS5LM also supports GGUF decision models with llama.cpp decision metadata, including d1, Clef and OpenJev models. These models serve TypeSafe’s /v1/systemone API for typed choices, scores and yes-or-no responses about text and images. PS5LM requires a PS5 on firmware 7.00 through 13.60 with a jailbreak and specified homebrew payloads, including kstuff-lite, etaHEN and ShadowMountPlus.
github.com
5 min
1h ago
BeBox is a Haiku application that emulates Be Inc.'s BeBox
BeBox is a Haiku application that emulates Be Inc.’s dual-processor BeBox systems and earlier Hobbit-based prototypes. It runs the 66 MHz dual-PowerPC 603 BeBox and the 133 MHz dual-PowerPC 603e model from original boot ROMs, supporting PowerPC BeOS releases from Developer Release 6 through R5.0.3. The emulator includes PowerPC processors, the MPC105 bridge, writable flash ROM, NVRAM, SCSI, IDE, floppy storage, video, sound, serial ports, game ports and NE2000-compatible Ethernet. It displays the BeBox’s two columns of front-panel LEDs and can run both emulated processors on separate host CPU cores. The Hobbit mode emulates two 25 MHz AT&T 92010 processors and hardware used in Be prototypes from 1993-94. Because no Hobbit boot ROM survives, BeBox directly loads the prototype system kernel from a floppy or SCSI disk image. Hobbit emulation includes SCSI, floppy DMA, serial ports, keyboard, mouse and Trident VGA graphics, but not its DSPs, sound, Ethernet, joystick or parallel hardware. BeBox supports raw and QCOW2 disk images, overlays, Haiku shared folders mounted by BeOS as BFS disks, NAT-based networking and port forwarding. Original BeBox ROMs, BeOS media and prototype disk images are required separately and are not included.
github.com
13 min
13h ago
CEO fired developers to make room for AI. Developers create open source AI CEO
Open Executive is an Apache 2.0-licensed, open-source virtual executive team built by SenteLabsAI. It presents users with one executive persona while an orchestrator routes requests to eight specialists covering strategy, finance, people, legal basics and compliance, operations, marketing, product, and board communications. The system uses Anthropic’s Claude API by default, with claude-sonnet-4-6 for the executive and most specialists and claude-opus-4-7 with extended thinking for strategy, finance, legal, and board work. It can also use OpenRouter or OpenAI-compatible local model servers such as Ollama, LM Studio, vLLM, and llama.cpp. Each specialist retrieves built-in business knowledge and uploaded company documents from separate ChromaDB collections. A background claude-haiku-4-5 process extracts decisions, initiatives, and advice into SQLite after responses, allowing later sessions to receive prior-decision context. A built-in scheduler can surface follow-ups but requires the FastAPI service to run as a single instance to avoid duplicate actions. The stack includes Python 3.11, FastAPI, Next.js 15, Tailwind, ChromaDB, and SQLite. Users can access it through a web interface, CLI, Slack, email, Telegram, Google Chat, or Discord. Local setup requires Python 3.11+, Node 22+, and an API provider configuration; the first start downloads an approximately 90 MB embedding model.
github.com
13 min
8/27/2026
WebMCP: Teaching Your Website to Talk to AI Agents
WebMCP is a proposed web standard that lets websites expose structured JavaScript tools for AI agents to discover and invoke, replacing brittle screen-scraping of buttons, HTML and visual layouts. A page can register actions such as booking a table, checking out, filtering results or adding a to-do item, with JSON Schema definitions for their inputs and outputs. The tools execute within the user’s already open and authenticated browser tab, using site functions that already exist rather than requiring a separate automation bot. Google and Microsoft are developing WebMCP in the W3C Web Machine Learning Community Group. It remains a Community Group draft rather than a finished W3C standard or standards-track specification. Chrome offers it behind a testing flag, and the current API uses document.modelContext; earlier drafts used navigator.modelContext. ChatGPT supports WebMCP-enabled pages, according to an OpenAI Developers post dated August 26, 2026. The design includes same-origin tool registration through a tools Permissions Policy, visible execution in an open browsing context, optional confirmation for sensitive actions, and annotations including readOnlyHint and untrustedContentHint. These protections do not eliminate security risks, and the security model is still under development. WebMCP could enable agent-operated commerce, bookings, scheduling and support flows when sites explicitly expose the necessary tools and users approve consequential actions.
sreenathmenon.com
12 min
8/26/2026
Queryable Executables
SELF is an executable format that stores a program as a SQLite database, with executable segments represented as database rows. A Linux binfmt_misc interpreter maps those rows and transfers control to the program entry point, allowing executable contents and related metadata to be queried with SQL. The format can also let a running program open its own SQLite file through argv[0] and persist state in that same file; /proc/self/exe does not currently provide the original file in this setup. The self-httpd proof of concept packages a web server, website routes, visitor logs and button-press records into one SQLite database file. Its routes, visits and presses tables store page content and runtime data, while the server can query its own segments, symbols and relocations. A POST request to its /api/press endpoint inserts a button press into the executable’s database, and the live demonstration is hosted at selfdb.exe.xyz. SQLite transactions allow site content in the running file to be updated or rolled back without restarting the server. SQLite tools such as sqldiff can compare code, route and metadata changes between versions, and FTS5 can index pages stored in the executable. Deployments can copy a single file, while SQL INSERT ... SELECT statements can migrate tables such as visitor logs and button presses from an old file to a new build before it is swapped in.
fzakaria.com
7 min
8/26/2026
How the Claude Code team does code review
Anthropic’s Claude Code team has shifted most code review work to automated systems as AI agents generate a growing share of its software. Claude writes about 90% of Claude Code’s code, while merged pull requests more than doubled from June to September and the share requiring reverts fell by more than 40%, according to the team. Anthropic’s monorepo rose from roughly 2,500 changes per day in May to more than 30,000 in September. Every Claude Code pull request receives automated bug and security reviews before human review. Agents verify proposed findings, discard style-only or insufficiently supported comments, and rank remaining issues by severity. Automated checks include linting, type checks, builds, cross-platform tests, and merge-queue validation against the main branch. Changes are classified as low, medium, or high risk: low-risk changes can merge without human approval once automated checks pass, medium-risk changes need one human, and high-risk changes need two. Only trusted authors can use lighter review paths, and agent approvals never substitute for required human approvals. The team uses feature flags, staged latest-channel releases, on-call rotations, reverts, and incident reviews to limit damage from missed defects. It also evaluates reviewers daily against past incident-causing pull requests and tracks false-positive noise and review rounds. One pull request underwent more than 50 automated review-and-fix rounds overnight, prompting the team to measure rounds-to-pass and limit repeated review.
claude.dev
13 min
6h ago
BeBox is a Haiku application that emulates Be Inc.'s BeBox
BeBox is a Haiku application that emulates Be Inc.’s dual-processor BeBox systems and earlier Hobbit-based prototypes. It runs the 66 MHz dual-PowerPC 603 BeBox and the 133 MHz dual-PowerPC 603e model from original boot ROMs, supporting PowerPC BeOS releases from Developer Release 6 through R5.0.3. The emulator includes PowerPC processors, the MPC105 bridge, writable flash ROM, NVRAM, SCSI, IDE, floppy storage, video, sound, serial ports, game ports and NE2000-compatible Ethernet. It displays the BeBox’s two columns of front-panel LEDs and can run both emulated processors on separate host CPU cores. The Hobbit mode emulates two 25 MHz AT&T 92010 processors and hardware used in Be prototypes from 1993-94. Because no Hobbit boot ROM survives, BeBox directly loads the prototype system kernel from a floppy or SCSI disk image. Hobbit emulation includes SCSI, floppy DMA, serial ports, keyboard, mouse and Trident VGA graphics, but not its DSPs, sound, Ethernet, joystick or parallel hardware. BeBox supports raw and QCOW2 disk images, overlays, Haiku shared folders mounted by BeOS as BFS disks, NAT-based networking and port forwarding. Original BeBox ROMs, BeOS media and prototype disk images are required separately and are not included.
github.com
13 min
13h ago
Serve Markdown to AI Agents with Accept Headers
AcceptMarkdown.com promotes serving Markdown versions of web pages to AI agents through HTTP content negotiation. Clients can request a Markdown representation with the `Accept: text/markdown` header, allowing them to receive page content without navigation, scripts, styles, layout wrappers, advertisements, related-content sections, or modal overlays. The site says Markdown responses use a fraction of the bytes of full pages and can leave AI agents’ context windows focused on prose rather than DOM markup. It also says cleaner text can improve signal-to-noise for retrieval-augmented generation pipelines and that smaller responses can reduce fetching, parsing, and context-loading work before a model begins generating output. Its URL checker sends an edge request with `Accept: text/markdown` and reports what the origin returns. The checker evaluates whether a URL serves Markdown for that request, sets `Vary: Accept`, rejects unsupported content types with HTTP 406, and honors HTTP `q` quality values in Accept headers.
acceptmarkdown.com
1 min
8/26/2026
Queryable Executables
SELF is an executable format that stores a program as a SQLite database, with executable segments represented as database rows. A Linux binfmt_misc interpreter maps those rows and transfers control to the program entry point, allowing executable contents and related metadata to be queried with SQL. The format can also let a running program open its own SQLite file through argv[0] and persist state in that same file; /proc/self/exe does not currently provide the original file in this setup. The self-httpd proof of concept packages a web server, website routes, visitor logs and button-press records into one SQLite database file. Its routes, visits and presses tables store page content and runtime data, while the server can query its own segments, symbols and relocations. A POST request to its /api/press endpoint inserts a button press into the executable’s database, and the live demonstration is hosted at selfdb.exe.xyz. SQLite transactions allow site content in the running file to be updated or rolled back without restarting the server. SQLite tools such as sqldiff can compare code, route and metadata changes between versions, and FTS5 can index pages stored in the executable. Deployments can copy a single file, while SQL INSERT ... SELECT statements can migrate tables such as visitor logs and button presses from an old file to a new build before it is swapped in.
fzakaria.com
7 min
8/26/2026
Llama.cpp on a jailbroken PS5: run any GGUF model natively on the console
PS5LM is a homebrew application that runs GGUF language and decision models locally on jailbroken PlayStation 5 consoles using llama.cpp’s Vulkan backend and the console’s RDNA 2 GPU. It turns the PS5 into a private network model server without requiring a PC, cloud service or account while running. Devices on the local network can access OpenAI-compatible /v1/chat/completions and Anthropic-compatible /v1/messages endpoints at the console’s port 8081; Claude Code can use the Anthropic-compatible API. The application assigns up to 11.4 GB of shared PS5 memory to a model and its context, selects a context length and cache that fit available memory, and can download supported GGUF files from Hugging Face. Listed PS5 Slim performance includes 207 tokens per second for Qwen 3.5 0.8B Q4_K_M, 55 tokens per second for Qwen 3.5 9B Q4_K_M, and about 20 tokens per second with a 64,000-token context for Qwen 3.8 27B UD-Q2_K_XL. PS5LM also supports GGUF decision models with llama.cpp decision metadata, including d1, Clef and OpenJev models. These models serve TypeSafe’s /v1/systemone API for typed choices, scores and yes-or-no responses about text and images. PS5LM requires a PS5 on firmware 7.00 through 13.60 with a jailbreak and specified homebrew payloads, including kstuff-lite, etaHEN and ShadowMountPlus.
github.com
5 min
1h ago
Muse Spark Open
Meta has released the weights for Muse Spark Open, an open-weight, natively multimodal AI model designed for coding, agentic workflows, complex software engineering, and multi-step reasoning. The model has 816 billion total parameters, with 42 billion active parameters, and supports a context window of up to 1 million tokens. Meta calls it the most capable US open-weight model to date. Muse Spark Open can run locally on two Apple M5 Ultra Mac Studio systems using Apple’s MLX framework. Each M5 Ultra can provide up to 512 GB of unified memory and 1.2 TB/s of memory bandwidth, allowing the two systems to hold the full model. Meta tested on-device workflows with Muse Code, including making bug fixes and adding features to the Ice Cubes Mastodon client, as well as reviewing and vertically cropping video in DaVinci Resolve. The weights are available through Amazon SageMaker AI, Google Cloud Model Garden, Hugging Face, and Microsoft Foundry Models, while hosted inference is offered through Baseten, Fireworks AI, Groq, Modal, Nebius, OpenRouter, and Together AI. The model supports engines including SGLang, vLLM, TensorRT-LLM, Transformers, MLX, llama.cpp, and Unsloth. Meta says its SGLang kernels deliver 1.03-3.95 times kernel-level speedups on NVIDIA and AMD GPUs. The model is released under the Muse Model License with limited commercial terms.
research.meta.ai
3 min
1d ago
WebMCP: Teaching Your Website to Talk to AI Agents
WebMCP is a proposed web standard that lets websites expose structured JavaScript tools for AI agents to discover and invoke, replacing brittle screen-scraping of buttons, HTML and visual layouts. A page can register actions such as booking a table, checking out, filtering results or adding a to-do item, with JSON Schema definitions for their inputs and outputs. The tools execute within the user’s already open and authenticated browser tab, using site functions that already exist rather than requiring a separate automation bot. Google and Microsoft are developing WebMCP in the W3C Web Machine Learning Community Group. It remains a Community Group draft rather than a finished W3C standard or standards-track specification. Chrome offers it behind a testing flag, and the current API uses document.modelContext; earlier drafts used navigator.modelContext. ChatGPT supports WebMCP-enabled pages, according to an OpenAI Developers post dated August 26, 2026. The design includes same-origin tool registration through a tools Permissions Policy, visible execution in an open browsing context, optional confirmation for sensitive actions, and annotations including readOnlyHint and untrustedContentHint. These protections do not eliminate security risks, and the security model is still under development. WebMCP could enable agent-operated commerce, bookings, scheduling and support flows when sites explicitly expose the necessary tools and users approve consequential actions.
sreenathmenon.com
12 min
8/26/2026
Any window from your Mac, on your iPhone and iPad
Sill is a free, open-source Mac, iPhone, and iPad application that streams either one Mac window or the entire desktop to a paired mobile device and returns touch, keyboard, trackpad, mouse, scrolling, and Apple Pencil input to the Mac. Sill for Mac captures content with ScreenCaptureKit, encodes it as HEVC using VideoToolbox, and sends it directly to the iPhone or iPad app over TLS 1.3. It drops delayed frames rather than queueing them to keep the displayed image current. The software works on Apple-silicon Macs running macOS 14 or later and iPhones or iPads running iOS or iPadOS 17 or later. Devices can connect over a shared local network, USB, peer-to-peer Wi-Fi through Direct Wireless Connection, or a user-managed VPN or forwarded router port with Remote Access enabled. Each device is paired once using a 12-digit code or USB, and subsequent connections are pinned to the paired keys. Sill has no account, intermediary server, ads, tracking, or subscription. It supports bidirectional text clipboard sharing up to 256 KB, but does not stream Mac audio and shows only one window or the desktop at a time. The Mac app requires Screen Recording and Accessibility permissions; the latter lets it generate mouse and keyboard events and resize streamed windows. Sill is available as a notarized Mac download, through Homebrew, and as a free iPhone and iPad App Store app under the Apache 2.0 license.
github.com
9 min
19h ago
CEO fired developers to make room for AI. Developers create open source AI CEO
Open Executive is an Apache 2.0-licensed, open-source virtual executive team built by SenteLabsAI. It presents users with one executive persona while an orchestrator routes requests to eight specialists covering strategy, finance, people, legal basics and compliance, operations, marketing, product, and board communications. The system uses Anthropic’s Claude API by default, with claude-sonnet-4-6 for the executive and most specialists and claude-opus-4-7 with extended thinking for strategy, finance, legal, and board work. It can also use OpenRouter or OpenAI-compatible local model servers such as Ollama, LM Studio, vLLM, and llama.cpp. Each specialist retrieves built-in business knowledge and uploaded company documents from separate ChromaDB collections. A background claude-haiku-4-5 process extracts decisions, initiatives, and advice into SQLite after responses, allowing later sessions to receive prior-decision context. A built-in scheduler can surface follow-ups but requires the FastAPI service to run as a single instance to avoid duplicate actions. The stack includes Python 3.11, FastAPI, Next.js 15, Tailwind, ChromaDB, and SQLite. Users can access it through a web interface, CLI, Slack, email, Telegram, Google Chat, or Discord. Local setup requires Python 3.11+, Node 22+, and an API provider configuration; the first start downloads an approximately 90 MB embedding model.
github.com
13 min
8/27/2026
RAG Is Simpler Than You Think
Retrieval-augmented generation systems can begin with BM25 or other full-text search rather than embeddings and vector databases, particularly for keyword-heavy queries, exact identifiers, proprietary terminology, low query volumes, and frequently changing content. The source recommends measuring a baseline for two to four weeks, then adding complexity only when user feedback and evaluation data show that simpler retrieval fails. Full-text search avoids embedding API costs, document chunking, re-indexing, and model-deprecation risks; it can return results in under 10 milliseconds, according to the source. LLM-based query rewriting can convert conversational requests into keyword searches, add synonyms, preserve internal product names, and decompose complex questions at an estimated cost of about $0.001 per query using GPT-4o-mini. Hybrid retrieval uses BM25 to select 50 to 100 candidates and embeddings to rerank the top results, trading stronger semantic matching for roughly 200–500 milliseconds of added latency when documents are embedded on demand. On-the-fly embedding suits high-churn data, while hot/cold tiers pre-embed commonly accessed documents and process less-used material dynamically. Full pre-embedding is presented as appropriate for stable corpora, broad access patterns, more than 10,000 daily queries, and sub-50-millisecond latency requirements. The source estimates that 60% of systems can stop at full-text search plus query rewriting.
lighthousenewsletter.com
13 min
8/26/2026