Hot Chips 2026: CUDA Targets RISC-V – By Chester Lam
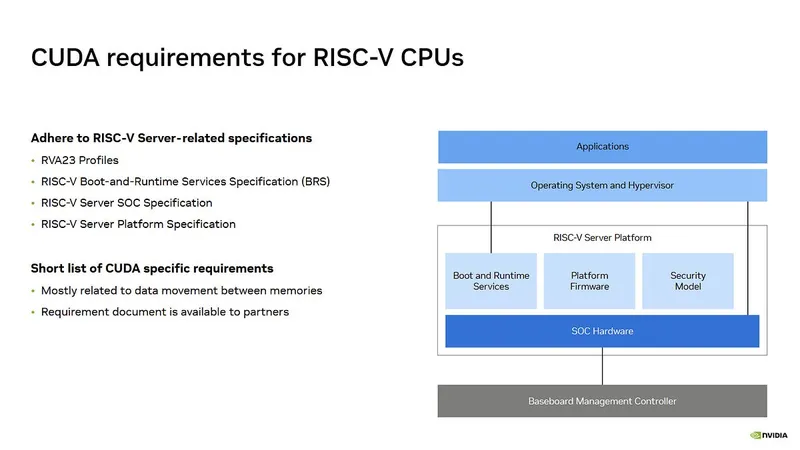
Nvidia is extending CUDA support toward RISC-V CPUs, potentially allowing server-class RISC-V systems to host Nvidia GPU compute workloads. CUDA currently supports x86-64 and AArch64 CPUs. Nvidia requires RISC-V systems to use the RVA23 profile and comply with RISC-V server SoC and platform specifications, which cover baseline reliability, availability, serviceability and security features. Nvidia also requires hardware features beyond those specifications, including vector extensions, PCIe cache coherency and peer-to-peer PCIe communication between devices. PCIe coherency prevents GPU DMA transfers from missing modified CPU-cache data or leaving CPUs with stale cached data after GPU writes. Without it, CUDA software would need explicit cache invalidation handling. Peer-to-peer PCIe support allows device-to-device buffer transfers without routing data through CPU memory. ACPI support was another initial obstacle, but the UEFI Forum added RISC-V ACPI support in 2025, and the ratified RISC-V Boot and Runtime Services specification includes ACPI. Nvidia said it is partnering with SiFive, which plans to demonstrate a CUDA-capable system at Hot Chips; the cited example specifications indicate a high-core-count server processor. Nvidia also described NVLink Fusion, which lets partners integrate Nvidia NVLink IP with custom CPUs or accelerators, including potential RISC-V designs, subject to CUDA requirements and support for frameworks such as DOCA and NCCL.
chipsandcheese.com
5 min
8/24/2026
Auto-research with codex: How I achieved a 232x Faster Kernel
Codex was utilized to achieve a 232x faster kernel for the qr_v2 problem in GPU mode. The implementation involved optimizing the blocked Householder algorithm and introducing idea diversity to enhance performance.
sankalp.bearblog.dev
26 min
8/15/2026
Self-hosting Kimi K3: 20% more hardware cost, 20% better task resolution
Kimi K3 requires an 8ÃB300 node with 288GB of HBM per GPU due to its 1.4TB weight, exceeding the memory capacity of the 8ÃB200 node. This configuration results in approximately 20% higher hardware costs while supporting 16 concurrent sessions.
aistack.imec-int.com
25 min
7/29/2026
RTX 5080 and RTX 3090 Setup: 80 Tok/s on Qwen 3.6 27B Q8
An RTX 5080 and RTX 3090 setup achieves over 80 tokens per second on the Qwen 3.6 27B Q8 model. The RTX 3090, with 24GB of memory, significantly enhances performance, allowing for initial speeds of 30 tokens per second, increasing to 50-60 tokens per second with MTP.
imil.net
5 min
6/13/2026
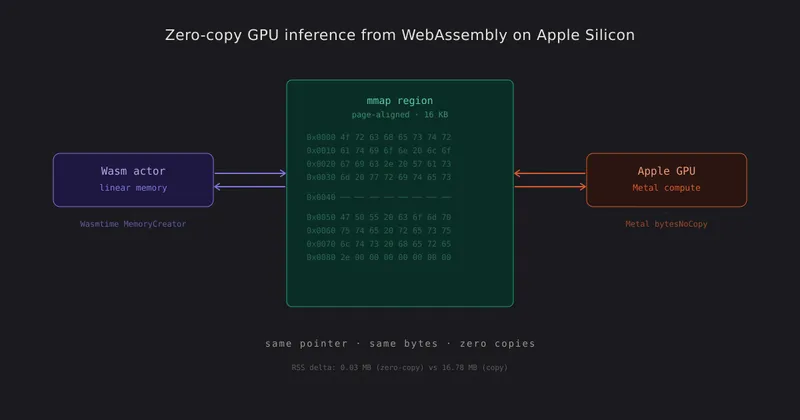
Zero-Copy GPU Inference from WebAssembly on Apple Silicon
WebAssembly modules on Apple Silicon can share linear memory directly with the GPU, eliminating the need for copies, serialization, or intermediate buffers. This allows the CPU and GPU to read and write the same physical bytes, enabling efficient end-to-end computation without serialization overhead.
abacusnoir.com
7 min
4/18/2026
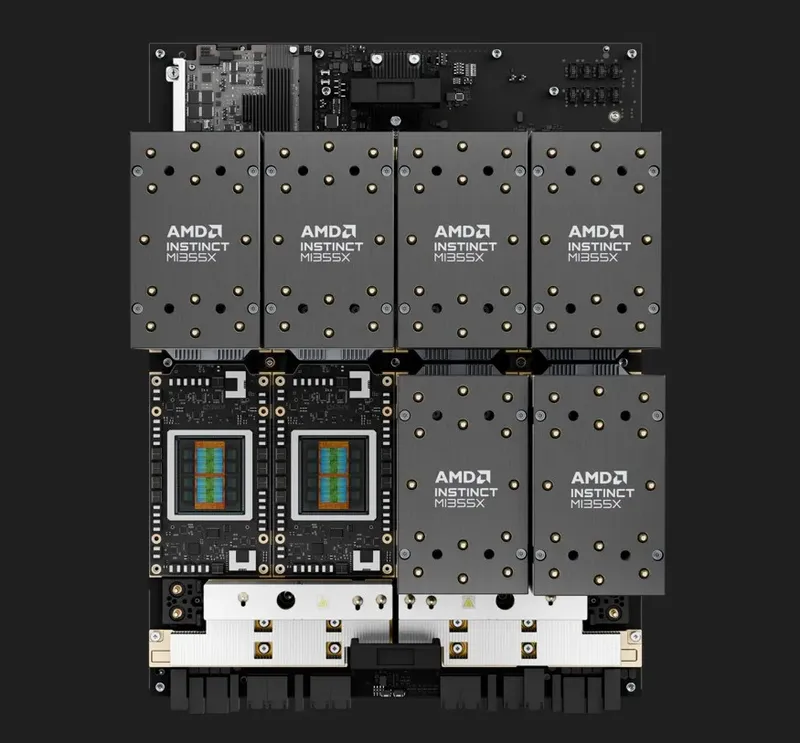
MegaTrain: Full Precision Training of 100B+ Parameter LLMs on a Single GPU
MegaTrain is a memory-centric system that enables the full precision training of large language models with over 100 billion parameters on a single GPU. It utilizes host memory to store parameters and optimizer states, treating GPUs as transient computation units.
arxiv.org
2 min
4/8/2026
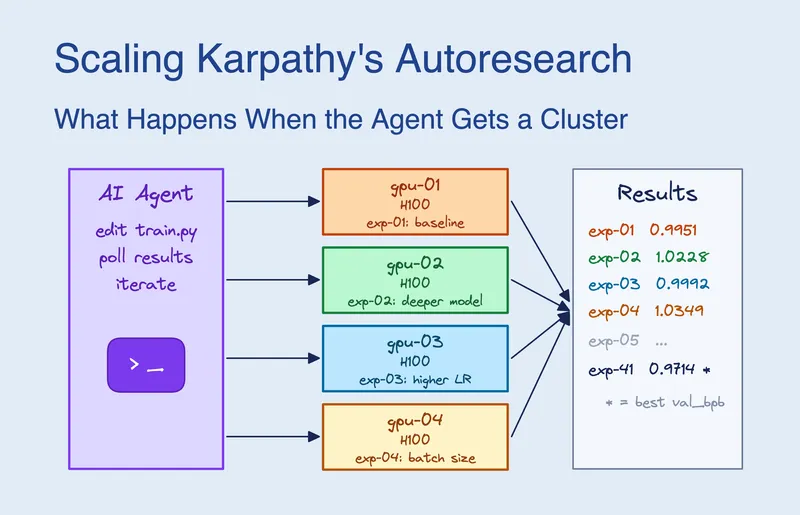
Scaling Karpathy's Autoresearch: What Happens When the Agent Gets a GPU Cluster
Claude Code was given access to 16 GPUs on a Kubernetes cluster and submitted approximately 910 experiments over 8 hours. It determined that scaling model width was more significant than any single hyperparameter and achieved a 2.87% improvement in validation performance, reducing val_bpb from 1.003 to 0.974.
blog.skypilot.co
12 min
3/19/2026
A CPU that runs entirely on GPU
nCPU is a CPU architecture that operates entirely on GPU, utilizing tensors for registers, memory, flags, and the program counter. All arithmetic operations, including addition, multiplication, bitwise operations, and shifts, are performed through trained neural networks, with specific methods like Kogge-Stone carry-lookahead for addition and learned byte-pair lookup tables for multiplication.
github.com
8 min
3/4/2026
Hot Chips 2026: CUDA Targets RISC-V – By Chester Lam
Nvidia is extending CUDA support toward RISC-V CPUs, potentially allowing server-class RISC-V systems to host Nvidia GPU compute workloads. CUDA currently supports x86-64 and AArch64 CPUs. Nvidia requires RISC-V systems to use the RVA23 profile and comply with RISC-V server SoC and platform specifications, which cover baseline reliability, availability, serviceability and security features. Nvidia also requires hardware features beyond those specifications, including vector extensions, PCIe cache coherency and peer-to-peer PCIe communication between devices. PCIe coherency prevents GPU DMA transfers from missing modified CPU-cache data or leaving CPUs with stale cached data after GPU writes. Without it, CUDA software would need explicit cache invalidation handling. Peer-to-peer PCIe support allows device-to-device buffer transfers without routing data through CPU memory. ACPI support was another initial obstacle, but the UEFI Forum added RISC-V ACPI support in 2025, and the ratified RISC-V Boot and Runtime Services specification includes ACPI. Nvidia said it is partnering with SiFive, which plans to demonstrate a CUDA-capable system at Hot Chips; the cited example specifications indicate a high-core-count server processor. Nvidia also described NVLink Fusion, which lets partners integrate Nvidia NVLink IP with custom CPUs or accelerators, including potential RISC-V designs, subject to CUDA requirements and support for frameworks such as DOCA and NCCL.
chipsandcheese.com
5 min
8/24/2026
Self-hosting Kimi K3: 20% more hardware cost, 20% better task resolution
Kimi K3 requires an 8ÃB300 node with 288GB of HBM per GPU due to its 1.4TB weight, exceeding the memory capacity of the 8ÃB200 node. This configuration results in approximately 20% higher hardware costs while supporting 16 concurrent sessions.
aistack.imec-int.com
25 min
7/29/2026
Zero-Copy GPU Inference from WebAssembly on Apple Silicon
WebAssembly modules on Apple Silicon can share linear memory directly with the GPU, eliminating the need for copies, serialization, or intermediate buffers. This allows the CPU and GPU to read and write the same physical bytes, enabling efficient end-to-end computation without serialization overhead.
abacusnoir.com
7 min
4/18/2026
MegaTrain: Full Precision Training of 100B+ Parameter LLMs on a Single GPU
MegaTrain is a memory-centric system that enables the full precision training of large language models with over 100 billion parameters on a single GPU. It utilizes host memory to store parameters and optimizer states, treating GPUs as transient computation units.
arxiv.org
2 min
4/8/2026
A CPU that runs entirely on GPU
nCPU is a CPU architecture that operates entirely on GPU, utilizing tensors for registers, memory, flags, and the program counter. All arithmetic operations, including addition, multiplication, bitwise operations, and shifts, are performed through trained neural networks, with specific methods like Kogge-Stone carry-lookahead for addition and learned byte-pair lookup tables for multiplication.
github.com
8 min
3/4/2026
Auto-research with codex: How I achieved a 232x Faster Kernel
Codex was utilized to achieve a 232x faster kernel for the qr_v2 problem in GPU mode. The implementation involved optimizing the blocked Householder algorithm and introducing idea diversity to enhance performance.
sankalp.bearblog.dev
26 min
8/15/2026
RTX 5080 and RTX 3090 Setup: 80 Tok/s on Qwen 3.6 27B Q8
An RTX 5080 and RTX 3090 setup achieves over 80 tokens per second on the Qwen 3.6 27B Q8 model. The RTX 3090, with 24GB of memory, significantly enhances performance, allowing for initial speeds of 30 tokens per second, increasing to 50-60 tokens per second with MTP.
imil.net
5 min
6/13/2026
Taking on CUDA with ROCm: 'One Step After Another'
AMD's ROCm software stack aims to compete with Nvidia's CUDA for data center GPU market share. Success in this endeavor is viewed as a significant challenge due to CUDA's established dominance.
eetimes.com
6 min
4/12/2026
Scaling Karpathy's Autoresearch: What Happens When the Agent Gets a GPU Cluster
Claude Code was given access to 16 GPUs on a Kubernetes cluster and submitted approximately 910 experiments over 8 hours. It determined that scaling model width was more significant than any single hyperparameter and achieved a 2.87% improvement in validation performance, reducing val_bpb from 1.003 to 0.974.
blog.skypilot.co
12 min
3/19/2026
Hot Chips 2026: CUDA Targets RISC-V – By Chester Lam
Nvidia is extending CUDA support toward RISC-V CPUs, potentially allowing server-class RISC-V systems to host Nvidia GPU compute workloads. CUDA currently supports x86-64 and AArch64 CPUs. Nvidia requires RISC-V systems to use the RVA23 profile and comply with RISC-V server SoC and platform specifications, which cover baseline reliability, availability, serviceability and security features. Nvidia also requires hardware features beyond those specifications, including vector extensions, PCIe cache coherency and peer-to-peer PCIe communication between devices. PCIe coherency prevents GPU DMA transfers from missing modified CPU-cache data or leaving CPUs with stale cached data after GPU writes. Without it, CUDA software would need explicit cache invalidation handling. Peer-to-peer PCIe support allows device-to-device buffer transfers without routing data through CPU memory. ACPI support was another initial obstacle, but the UEFI Forum added RISC-V ACPI support in 2025, and the ratified RISC-V Boot and Runtime Services specification includes ACPI. Nvidia said it is partnering with SiFive, which plans to demonstrate a CUDA-capable system at Hot Chips; the cited example specifications indicate a high-core-count server processor. Nvidia also described NVLink Fusion, which lets partners integrate Nvidia NVLink IP with custom CPUs or accelerators, including potential RISC-V designs, subject to CUDA requirements and support for frameworks such as DOCA and NCCL.
chipsandcheese.com
5 min
8/24/2026
RTX 5080 and RTX 3090 Setup: 80 Tok/s on Qwen 3.6 27B Q8
An RTX 5080 and RTX 3090 setup achieves over 80 tokens per second on the Qwen 3.6 27B Q8 model. The RTX 3090, with 24GB of memory, significantly enhances performance, allowing for initial speeds of 30 tokens per second, increasing to 50-60 tokens per second with MTP.
imil.net
5 min
6/13/2026
MegaTrain: Full Precision Training of 100B+ Parameter LLMs on a Single GPU
MegaTrain is a memory-centric system that enables the full precision training of large language models with over 100 billion parameters on a single GPU. It utilizes host memory to store parameters and optimizer states, treating GPUs as transient computation units.
arxiv.org
2 min
4/8/2026
Auto-research with codex: How I achieved a 232x Faster Kernel
Codex was utilized to achieve a 232x faster kernel for the qr_v2 problem in GPU mode. The implementation involved optimizing the blocked Householder algorithm and introducing idea diversity to enhance performance.
sankalp.bearblog.dev
26 min
8/15/2026
Zero-Copy GPU Inference from WebAssembly on Apple Silicon
WebAssembly modules on Apple Silicon can share linear memory directly with the GPU, eliminating the need for copies, serialization, or intermediate buffers. This allows the CPU and GPU to read and write the same physical bytes, enabling efficient end-to-end computation without serialization overhead.
abacusnoir.com
7 min
4/18/2026
Scaling Karpathy's Autoresearch: What Happens When the Agent Gets a GPU Cluster
Claude Code was given access to 16 GPUs on a Kubernetes cluster and submitted approximately 910 experiments over 8 hours. It determined that scaling model width was more significant than any single hyperparameter and achieved a 2.87% improvement in validation performance, reducing val_bpb from 1.003 to 0.974.
blog.skypilot.co
12 min
3/19/2026
Self-hosting Kimi K3: 20% more hardware cost, 20% better task resolution
Kimi K3 requires an 8ÃB300 node with 288GB of HBM per GPU due to its 1.4TB weight, exceeding the memory capacity of the 8ÃB200 node. This configuration results in approximately 20% higher hardware costs while supporting 16 concurrent sessions.
aistack.imec-int.com
25 min
7/29/2026
Taking on CUDA with ROCm: 'One Step After Another'
AMD's ROCm software stack aims to compete with Nvidia's CUDA for data center GPU market share. Success in this endeavor is viewed as a significant challenge due to CUDA's established dominance.
eetimes.com
6 min
4/12/2026
A CPU that runs entirely on GPU
nCPU is a CPU architecture that operates entirely on GPU, utilizing tensors for registers, memory, flags, and the program counter. All arithmetic operations, including addition, multiplication, bitwise operations, and shifts, are performed through trained neural networks, with specific methods like Kogge-Stone carry-lookahead for addition and learned byte-pair lookup tables for multiplication.
github.com
8 min
3/4/2026
No more articles to load