Top stories
Story · 1 report
Alleged Chinese spy had 'close relationship' with Nvidia boss Jensen Huang
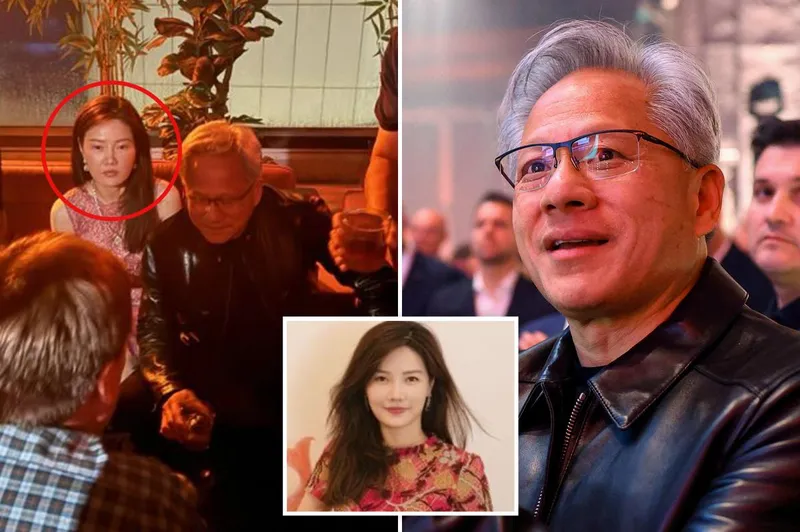
US intelligence agencies concluded that Alice Huang, a Chinese citizen and senior executive at Singapore-based cloud provider Megaspeed, secretly passed information to Beijing, according to the New York Times, which cited people briefed on classified findings. Electronic surveillance identified Nvidia CEO Jensen Huang as one of her contacts, but the Times reported no evidence that he knew of her alleged intelligence activities or what information she may have provided. Photos showed the two at a Taipei bar in June 2024 and after a business dinner in May 2025. Nvidia said Jensen Huang’s meetings with customer executives were routine and that regional cloud customers receive ordinary business information rather than trade secrets or national-security-relevant material. Megaspeed buys Nvidia chips through the US arm of Chinese server maker Inspur and rents computing capacity from Southeast Asian data centers to Chinese companies, including Alibaba. US authorities have investigated whether Megaspeed helped Chinese firms evade export restrictions and move advanced Nvidia chips into China, the Times reported. Nvidia rejected diversion allegations, saying they were investigated and debunked in 2025. The Times also reported that President Trump was briefed on the intelligence findings about a year earlier but did not act, partly over concerns about Nvidia sales and US-China trade. China’s embassy rejected the alleged-spy narrative as a groundless smear.
nypost.com
🔥🔥🔥🔥🔥2 min summary
3d ago
Story · 1 report
Nvidia Nemotron 3.5 Transcribe: open ASR for 40 languages
NVIDIA released Nemotron 3.5 Transcribe, an open-weight speech model available through Hugging Face and ModelScope that combines transcription, speaker attribution, English translation, and audio question answering in one checkpoint. It transcribes 40 languages, translates 31 languages to or from English, supports speaker attribution in 13 languages, processes recordings up to one hour, and labels as many as eight speakers. Natural-language prompts can request outputs such as speaker-labeled transcripts, translations, meeting decisions, or specified formatting for technical vocabulary. Audio question answering is trained in English, and NVIDIA advises users to verify names, speaker changes, and answers against recordings. NVIDIA reports that the model ranks first among open-weight models on the Hugging Face English Open ASR Leaderboard with 5.33% average word error rate, and ties for first on Artificial Analysis’s open-weight ranking at 2.8% AA-WER while activating about 4 billion of its 30 billion parameters per token. Granary v2 supplies an open data-curation pipeline and public manifests covering 463,062 hours of speech across 48 languages. In an NVIDIA medical-transcription case study using Eka Care recordings, fine-tuning reduced held-out-speaker word error rate from 22.44% with the best prompt to 12.17%, a 45.8% relative reduction. NVIDIA said forthcoming quantized versions will support local deployment, while the current checkpoint can be served with vLLM and is designed for recorded rather than live-streaming audio.
huggingface.co
🔥🔥🔥🔥🔥2 min summary
5d ago
Story · 1 report
Modders unlock hidden AI power on Nvidia RTX 20, 30, and 40 series GPUs, nearly doubling some benchmarks
Open-source tools claim to unlock higher tensor-core throughput on Nvidia GeForce RTX 20-, 30-, and 40-series GPUs by removing a performance limit applied to certain AI calculations. On these cards, FP16 or BF16 operations that accumulate results in FP32 run at half the rate of FP16-accumulate mode, while workstation GPUs using the same chips, such as Nvidia's RTX A6000, run the FP32-accumulate mode at full speed. The changes chiefly target AI training, inference prompt processing, image generation, and fine-tuning rather than games or chatbot token generation. GitHub user Zagitta's Linux kernel module, gpu-unlock, runs before Nvidia's driver loads, rewrites two GPU speed-selection registers, and resets the card without requiring a VBIOS flash or driver patch. On a 450W RTX 3090 Ti, its developer measured BF16 throughput rising from 87.5 to 157.4 TFLOPS and a near doubling in TF32 throughput, while FP16 increased 35%. Related projects include gpu-unlock-ada for RTX 40-series cards and turing-unlock for RTX 2080 Ti cards. gpu-unlock-ada doubled an RTX 4090's raw FP16 instruction rate from 165.6 to 331.6 TFLOPS, although independently tested real workloads gained 12% to 34%. Linux has most support; experimental Windows ports have been validated only on specific hardware. Developers differ on risk, with one warning sustained tensor-core use may damage hardware.
techspot.com
🔥🔥🔥🔥🔥2 min summary
4d ago
No more articles to load