It is a sign of the times that Amazon gets to call this fair use
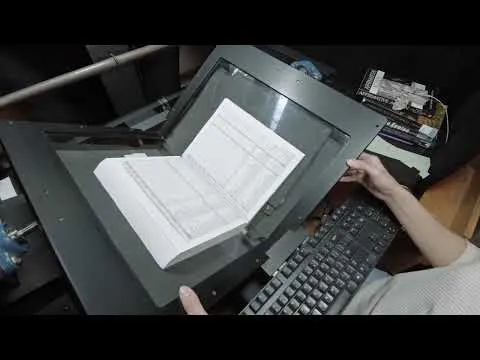
Amazon has reportedly bought large quantities of printed books, including rare and foreign-language titles, for scanning into AI training data. A 404 Media investigation tracked a rare book with a tracking device to Amazon’s VGT3 warehouse in Las Vegas, Nevada. Employees at the site reportedly said shipments of books are received there, their bindings are cut off to speed scanning, and the physical copies are destroyed. A bookseller involved in the tracked shipment said rare books can carry historical, intellectual, sentimental, and monetary value beyond their text. The Internet Archive, founded by Brewster Kahle in 1996, digitizes books while retaining their physical bindings. Its scanning centers use operators known as scribe operators to capture books one page at a time. The organization says it does not destroy books by cutting off their bindings and instead adapts machines and software for nondestructive digitization. The Internet Archive contrasts its process with Google Books, launched in 2004, which it says used industrial-scale destructive scanning to increase processing speed.
observationalepidemiology.blogspot.com
2 min
8/21/2026
Blocking Internet Archive Won't Stop AI, but Will Erase Web's Historical Record
The Internet Archive is the largest digital library, preserving over one trillion archived web pages through its Wayback Machine. Recent actions by publishers to block the Internet Archive threaten the preservation of the web's historical record.
eff.org
3 min
3/21/2026

News publishers limit Internet Archive access due to AI scraping concerns
News publishers are restricting access to the Internet Archive due to concerns over AI scraping of their content. The Internet Archive's crawlers capture webpage snapshots, which are accessible via the Wayback Machine, potentially exposing publishers' material to unauthorized use by AI models.
niemanlab.org
9 min
2/14/2026
It is a sign of the times that Amazon gets to call this fair use
Amazon has reportedly bought large quantities of printed books, including rare and foreign-language titles, for scanning into AI training data. A 404 Media investigation tracked a rare book with a tracking device to Amazon’s VGT3 warehouse in Las Vegas, Nevada. Employees at the site reportedly said shipments of books are received there, their bindings are cut off to speed scanning, and the physical copies are destroyed. A bookseller involved in the tracked shipment said rare books can carry historical, intellectual, sentimental, and monetary value beyond their text. The Internet Archive, founded by Brewster Kahle in 1996, digitizes books while retaining their physical bindings. Its scanning centers use operators known as scribe operators to capture books one page at a time. The organization says it does not destroy books by cutting off their bindings and instead adapts machines and software for nondestructive digitization. The Internet Archive contrasts its process with Google Books, launched in 2004, which it says used industrial-scale destructive scanning to increase processing speed.
observationalepidemiology.blogspot.com
2 min
8/21/2026
News publishers limit Internet Archive access due to AI scraping concerns
News publishers are restricting access to the Internet Archive due to concerns over AI scraping of their content. The Internet Archive's crawlers capture webpage snapshots, which are accessible via the Wayback Machine, potentially exposing publishers' material to unauthorized use by AI models.
niemanlab.org
9 min
2/14/2026
Blocking Internet Archive Won't Stop AI, but Will Erase Web's Historical Record
The Internet Archive is the largest digital library, preserving over one trillion archived web pages through its Wayback Machine. Recent actions by publishers to block the Internet Archive threaten the preservation of the web's historical record.
eff.org
3 min
3/21/2026
It is a sign of the times that Amazon gets to call this fair use
Amazon has reportedly bought large quantities of printed books, including rare and foreign-language titles, for scanning into AI training data. A 404 Media investigation tracked a rare book with a tracking device to Amazon’s VGT3 warehouse in Las Vegas, Nevada. Employees at the site reportedly said shipments of books are received there, their bindings are cut off to speed scanning, and the physical copies are destroyed. A bookseller involved in the tracked shipment said rare books can carry historical, intellectual, sentimental, and monetary value beyond their text. The Internet Archive, founded by Brewster Kahle in 1996, digitizes books while retaining their physical bindings. Its scanning centers use operators known as scribe operators to capture books one page at a time. The organization says it does not destroy books by cutting off their bindings and instead adapts machines and software for nondestructive digitization. The Internet Archive contrasts its process with Google Books, launched in 2004, which it says used industrial-scale destructive scanning to increase processing speed.
observationalepidemiology.blogspot.com
2 min
8/21/2026
Blocking Internet Archive Won't Stop AI, but Will Erase Web's Historical Record
The Internet Archive is the largest digital library, preserving over one trillion archived web pages through its Wayback Machine. Recent actions by publishers to block the Internet Archive threaten the preservation of the web's historical record.
eff.org
3 min
3/21/2026
News publishers limit Internet Archive access due to AI scraping concerns
News publishers are restricting access to the Internet Archive due to concerns over AI scraping of their content. The Internet Archive's crawlers capture webpage snapshots, which are accessible via the Wayback Machine, potentially exposing publishers' material to unauthorized use by AI models.
niemanlab.org
9 min
2/14/2026
No more articles to load