Latest stories
Story · 1 report
So I guess everyone uses LLMs to think now
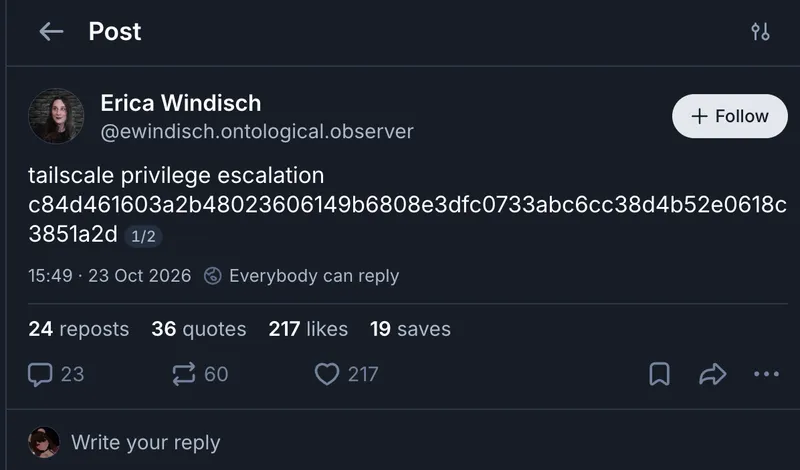
Eva, a security researcher and blogger, says she has never used AI for research published on her site and prefers manual coding, debugging, reverse engineering, source-code exploration, and vulnerability research. She says LLM output can be confidently wrong and frustrating to supervise, while acknowledging that the models are powerful. Eva argues that current LLMs still require skilled human guidance; she says an unguided model would probably not find a Linux kernel remote-code-execution vulnerability on its own. Eva criticizes AI companies’ cybersecurity marketing, citing differing accounts of the php2shell research collaboration involving Calif, OpenAI, and Wiz. She says OpenAI emphasized an agent uncovering critical vulnerabilities, while Calif described human-guided AI research. Eva also argues that publishing proof-of-concept videos, product-linked hashes, or cryptic vulnerability announcements before patches are available can create unnecessary risk and panic. She cites a publicly disclosed Tailscale SSH privilege-escalation issue that she says required existing ACL access to a machine with Tailscale SSH enabled, and alleges it was not responsibly disclosed to Tailscale before publication. Eva contrasts AI-assisted findings with the eMudhra certificate-authority private-key incident, which she says a human discovered using Google’s paranoid_crypto library. She argues that personal projects provide learning and enjoyment that AI-generated work can reduce.
eva.ac
🔥🔥🔥🔥🔥2 min summary
4d ago
No more articles to load