Turbovec – Google's TurboQuant for vector search in Rust
turbovec is a Rust vector index with Python bindings that implements Google Research’s TurboQuant quantization algorithm for approximate nearest-neighbor search. It accepts float32 vectors, supports online ingestion without a separate training phase, and provides full-file snapshots plus incremental, crash-safe sync operations. Its IdMapIndex variant supports stable uint64 external IDs and O(1) deletions. Search can apply ID allowlists or slot bitmasks inside SIMD kernels, returning up to k results only from permitted vectors. The project claims that a 10 million-document corpus requiring 31 GB as float32 fits in 4 GB with turbovec. On 100,000-vector benchmarks using OpenAI 1,536- and 3,072-dimensional embeddings and GloVe 200-dimensional vectors, its maintainers report TurboQuant search outperformed FAISS IndexPQFastScan in every measured ARM and x86 configuration: averages were 3.4–3.5 times faster at 4-bit quantization and 20–26% faster at 2-bit. The reported recall results varied by embedding dimension and bit width, with calibrated TQ+ generally matching or exceeding FAISS at recall@1 in tested OpenAI configurations. TurboQuant normalizes vectors, applies a shared random rotation, quantizes coordinates into 2- or 4-bit codes, and scores compressed vectors directly using NEON, AVX-512, AVX2, or scalar kernels. Optional TQ+ calibration fits per-coordinate shifts and scales from a representative sample before ingestion.
github.com
12 min
8/19/2026
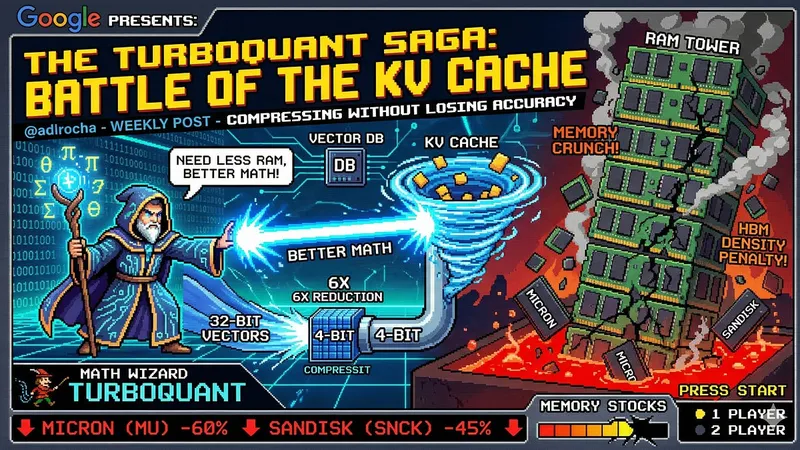
What if AI doesn't need more RAM but better math?
TurboQuant compresses the KV cache in AI applications, improving efficiency without sacrificing accuracy. This innovation addresses the challenges of HBM density penalties and DRAM price pressures in the AI memory landscape.
adlrocha.substack.com
10 min
3/29/2026
Turbovec – Google's TurboQuant for vector search in Rust
turbovec is a Rust vector index with Python bindings that implements Google Research’s TurboQuant quantization algorithm for approximate nearest-neighbor search. It accepts float32 vectors, supports online ingestion without a separate training phase, and provides full-file snapshots plus incremental, crash-safe sync operations. Its IdMapIndex variant supports stable uint64 external IDs and O(1) deletions. Search can apply ID allowlists or slot bitmasks inside SIMD kernels, returning up to k results only from permitted vectors. The project claims that a 10 million-document corpus requiring 31 GB as float32 fits in 4 GB with turbovec. On 100,000-vector benchmarks using OpenAI 1,536- and 3,072-dimensional embeddings and GloVe 200-dimensional vectors, its maintainers report TurboQuant search outperformed FAISS IndexPQFastScan in every measured ARM and x86 configuration: averages were 3.4–3.5 times faster at 4-bit quantization and 20–26% faster at 2-bit. The reported recall results varied by embedding dimension and bit width, with calibrated TQ+ generally matching or exceeding FAISS at recall@1 in tested OpenAI configurations. TurboQuant normalizes vectors, applies a shared random rotation, quantizes coordinates into 2- or 4-bit codes, and scores compressed vectors directly using NEON, AVX-512, AVX2, or scalar kernels. Optional TQ+ calibration fits per-coordinate shifts and scales from a representative sample before ingestion.
github.com
12 min
8/19/2026
What if AI doesn't need more RAM but better math?
TurboQuant compresses the KV cache in AI applications, improving efficiency without sacrificing accuracy. This innovation addresses the challenges of HBM density penalties and DRAM price pressures in the AI memory landscape.
adlrocha.substack.com
10 min
3/29/2026
Turbovec – Google's TurboQuant for vector search in Rust
turbovec is a Rust vector index with Python bindings that implements Google Research’s TurboQuant quantization algorithm for approximate nearest-neighbor search. It accepts float32 vectors, supports online ingestion without a separate training phase, and provides full-file snapshots plus incremental, crash-safe sync operations. Its IdMapIndex variant supports stable uint64 external IDs and O(1) deletions. Search can apply ID allowlists or slot bitmasks inside SIMD kernels, returning up to k results only from permitted vectors. The project claims that a 10 million-document corpus requiring 31 GB as float32 fits in 4 GB with turbovec. On 100,000-vector benchmarks using OpenAI 1,536- and 3,072-dimensional embeddings and GloVe 200-dimensional vectors, its maintainers report TurboQuant search outperformed FAISS IndexPQFastScan in every measured ARM and x86 configuration: averages were 3.4–3.5 times faster at 4-bit quantization and 20–26% faster at 2-bit. The reported recall results varied by embedding dimension and bit width, with calibrated TQ+ generally matching or exceeding FAISS at recall@1 in tested OpenAI configurations. TurboQuant normalizes vectors, applies a shared random rotation, quantizes coordinates into 2- or 4-bit codes, and scores compressed vectors directly using NEON, AVX-512, AVX2, or scalar kernels. Optional TQ+ calibration fits per-coordinate shifts and scales from a representative sample before ingestion.
github.com
12 min
8/19/2026
What if AI doesn't need more RAM but better math?
TurboQuant compresses the KV cache in AI applications, improving efficiency without sacrificing accuracy. This innovation addresses the challenges of HBM density penalties and DRAM price pressures in the AI memory landscape.
adlrocha.substack.com
10 min
3/29/2026
No more articles to load