DeepSeek V4 Flash on a Single AMD MI300X
github.com
August 4, 2026
10 min read
65/100
Summary
The GitHub repository ryanzhou/deepseek-v4-flash-mi300x provides configuration and patches for running DeepSeek-V4-Flash-0731 on an AMD MI300X. It includes a Docker Compose stack, SHA-256-pinned file overlays, reference diffs, tuning tables, and runs checkpoints without additional weight quantization or offload.
Key Takeaways
- The repository provides configuration and patches for running DeepSeek-V4-Flash-0731 on an AMD MI300X, including Docker Compose stack and tuning tables.
- The MI300X can handle up to 64 concurrent streams with a single GPU deployment, utilizing 156.67 GiB of HBM without additional weight quantization or offload.
- The repository includes fixes for FP8 format compatibility, MoE routing, and performance tuning specific to the MI300X architecture.
- The setup achieves a median single-stream decode rate of 168.6 tokens per second and an aggregate burst rate of 830 tokens per second across 64 streams.
Coverage & discussions
Hacker News · github.com
Community discussions
Community Sentiment
Positives
- The DeepSeek V4 Flash can run effectively on the MI350P, making it accessible for more users than the MI300X, which is a win for practical applications.
- Despite the context window reduction, achieving over 150 tokens/second is impressive and shows that performance isn't compromised too much.
- The potential for using the MI350P in servers while still maintaining high memory efficiency is a promising development for AI deployment.
Concerns
- The need to cut down the context window size from 1M to 256k is a significant tradeoff that could limit the model's usability in complex tasks.
- Commenters are skeptical about the MI300's performance compared to the H800, suggesting that there are optimizations still needed to truly compete.
- There's a sense that quantization techniques might be dumbing down the model, raising concerns about the balance between size and quality.
Related Articles

Bringing Up DeepSeek-V4-Flash on AMD MI300X
Jun 2, 2026
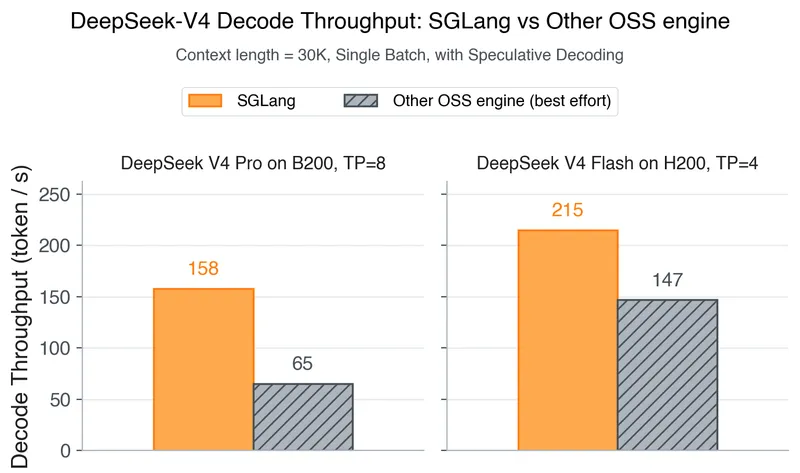
DeepSeek-V4 on Day 0: From Fast Inference to Verified RL with SGLang and Miles
Apr 25, 2026
Flash-MoE: Running a 397B Parameter Model on a Laptop
Mar 22, 2026
DeepSeek 4 Flash local inference engine for Metal
May 7, 2026
We got 207 tok/s with Qwen3.5-27B on an RTX 3090
Apr 20, 2026