Unified Memory, Explained: Why Mini PCs Can Run 70B Models a Big GPU Can't
vettedconsumer.com
July 10, 2026
11 min read
🔥🔥🔥🔥🔥
47/100
Summary
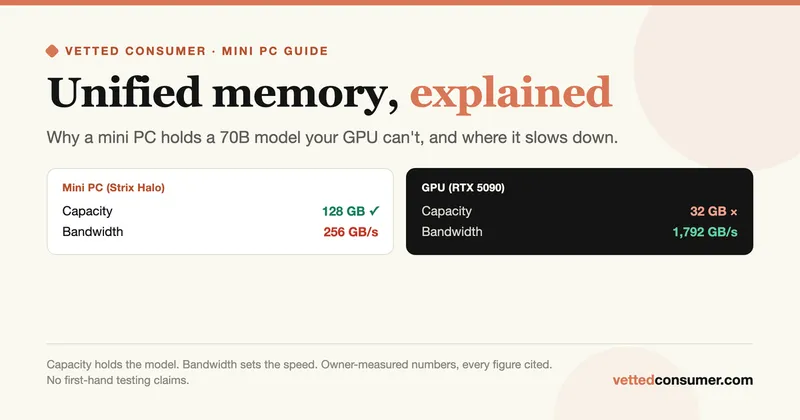
Mini PCs with unified memory can run 70-billion-parameter models due to their larger memory capacity, while high-end GPUs like the NVIDIA RTX 5090 are limited by their smaller memory size. The RTX 5090 has 32GB of memory, insufficient for a 70B model requiring approximately 40GB, whereas the mini PC can handle it with 128GB of memory.
Key Takeaways
- Mini PCs with unified memory can run 70-billion-parameter models due to their ability to allocate a larger pool of memory, while traditional GPUs like the NVIDIA RTX 5090 are limited by their separate VRAM capacity.
- Unified memory architecture allows CPUs and GPUs to share a single pool of memory, enabling configurations with up to 128GB of usable memory for models at a lower cost compared to high-end GPUs.
- The performance of machines for local LLMs is determined by two key specifications: capacity, which affects whether a model can load, and memory bandwidth, which affects the speed of text generation.
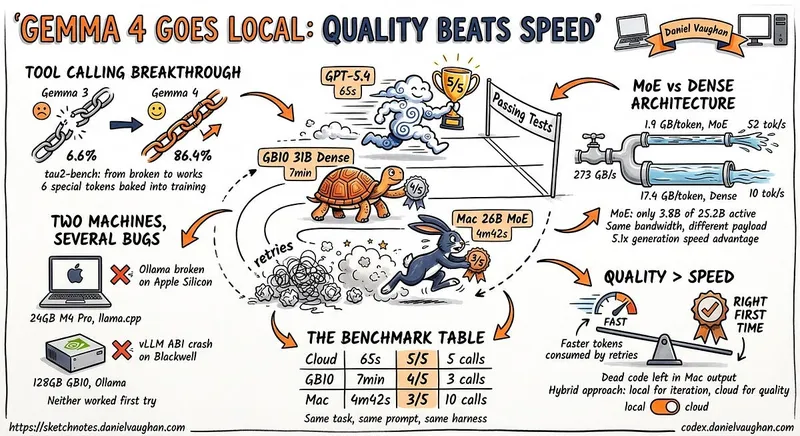
- While mini PCs excel in memory capacity, they lag behind GPUs in memory bandwidth, with peak bandwidth figures for mini PCs ranging from 120 to 273 GB/s compared to GPUs that can exceed 1,000 GB/s.
Coverage & discussions
Hacker News · vettedconsumer.com
Community discussions
Community Sentiment
Positives
- Unified memory architecture is a game changer, allowing mini PCs to handle 70B models with astonishing speed and efficiency — a big win for accessibility in AI.
- With the right batching techniques, you can achieve prefill speeds that rival setups with all weights in VRAM — this opens doors for more efficient AI deployments.
- The AMD Ryzen AI Max+ 395 is proving that powerful AI can come in compact packages, making high-performance computing more accessible without the need for bulky setups.
Concerns
- There's skepticism about the real-world performance when switching weights between RAM and VRAM — it can slow things down significantly, leading to frustrating bottlenecks.
- MoE models might be cheap to train, but they struggle with inference in local setups, which could limit their practical use for many developers.
- Concerns about how unified memory architectures handle memory shortages remain, leaving some questioning their reliability in high-demand scenarios.