What Is RLCD? The Secret Behind Jev
di-zhang-llm.github.io
September 24, 2026
12 min read
🔥🔥🔥🔥🔥
45/100
Summary
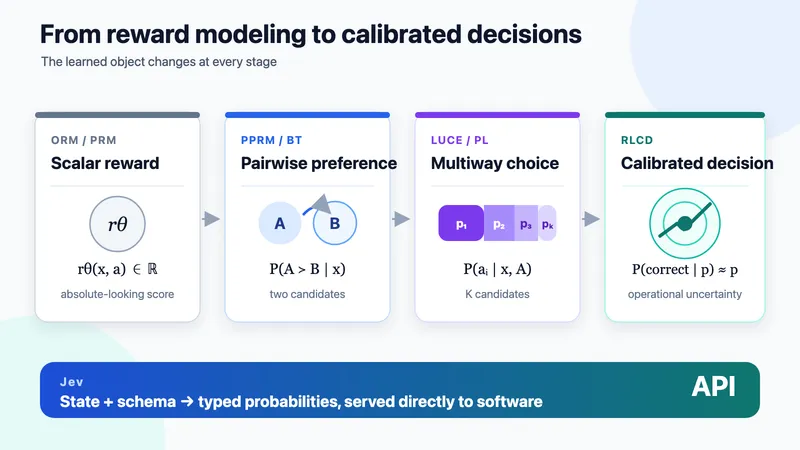
From pairwise reward modeling to calibrated, multiway decisions Jev looks mysterious when viewed as an alternative to a language model. It becomes much simpler when viewed as the next step in reward modeling. The core idea is: More specifically, RLCD is a schema-conditioned Plackett–Luce objective. Jev turns that objective into a product by adding typed outputs and parallel inference. That is the ...