When LLM judges agree, should we believe them?
amazon.science
September 14, 2026
5 min read
🔥🔥🔥🔥🔥
43/100
Summary
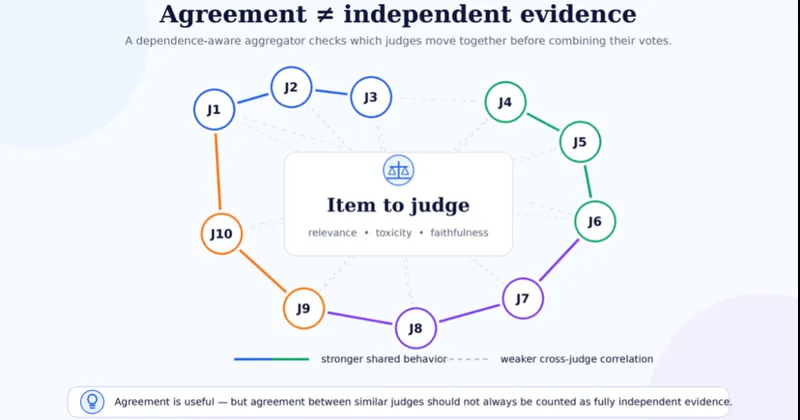
Imagine evaluating a retrieval-augmented-generation system. A user asks a question, the system retrieves a text passage, and an LLM judge decides whether it’s relevant. To reduce noise, you ask several judge models to evaluate the same passage. Eight say “relevant”; two say “not relevant”. Eight out of 10 feels convincing. But the important question is not only how many judges agreed but how indep...