ElevenLabs, TwelveLabs, ThirteenLabs
A post titled “ElevenLabs, TwelveLabs, ThirteenLabs” was published on quantumi.sh and attributed to jemoka. The post had a score of 108 points and 41 comments at the time of the supplied data. The supplied text provides no further details about ElevenLabs, TwelveLabs, ThirteenLabs, their products, or any claims associated with them.
quantumi.sh
1 min
8/22/2026

Micron announces $10B research hub in Boise
Micron Technology unveiled Micron Research Labs on August 20, 2026, a Boise-headquartered U.S. research institution focused on long-horizon advances in memory, computing and semiconductor manufacturing. The company plans to invest $10 billion in the labs over the next decade, funding a flagship Boise campus, university collaborations, global satellite labs and partnerships with government, startups, customers and other semiconductor-industry participants. Research will cover critical memory technologies, advanced memory and compute architectures, chip packaging, and future manufacturing methods. Micron said the institution will pursue work beyond current technology roadmaps and a 10-year horizon, while connecting its research operations across the United States, Europe, Japan, India, Singapore and Taiwan. The company expects to break ground on a facility capable of hosting hundreds of researchers in 2027; it is also expected to host conferences, workshops and innovation forums in Boise. The planned lab investment is separate from Micron’s previously announced commitment of more than $250 billion to U.S. manufacturing and research and development, which Micron says is expected to create more than 90,000 American jobs. Micron describes itself as the only U.S.-based company developing and manufacturing leading-edge memory.
investors.micron.com
9 min
8/21/2026
DiffusionGemma Technical Report
DiffusionGemma is an experimental open-weight language model that generates text through discrete diffusion, refining 256-token blocks in parallel rather than producing tokens sequentially. The design is intended to avoid the decoding bottleneck of autoregressive language models. The model was created by fine-tuning the mixture-of-experts Gemma 4 model, which has 3.8 billion activated parameters and 25.2 billion total parameters. Its two-stage training process used fewer than 10% of the original autoregressive model’s total training-token budget. Supervised fine-tuning first taught bidirectional denoising; a second phase combined reinforcement learning and sampler distillation to improve generation quality and inference efficiency. Across its evaluation suite, DiffusionGemma generated about 20 tokens per forward pass and about 1,500 output tokens per second on a single Nvidia H100 GPU. The researchers say these results establish a new speed-capability trade-off frontier and exceed autoregressive models, including those using speculative decoding. DiffusionGemma retains Gemma 4’s thinking mode, multimodal-input, and long-context support. It can also still generate text autoregressively with minor performance degradation, suggesting potential hybrid diffusion-autoregressive decoding systems.
arxiv.org
2 min
8/20/2026
Ornith-1.5: From Self-Scaffolding to Self-Improvement
Ornith introduced Ornith-1.5, a family of 397B-parameter mixture-of-experts (MoE), 35B MoE, and 9B dense models trained through a self-improvement loop. The system generates progressively harder tasks, creates task-specific scaffolds containing instructions, tools, decomposition, and orchestration, then produces reinforcement-learning rollouts. Rewards optimize task generation, scaffold construction, and solutions jointly using validity, frontier difficulty, novelty, solution quality, and resistance to reward hacking. The target task success rate is 0.2, favoring problems difficult enough to expose capability gaps while still yielding successful training trajectories. Ornith reports that its 397B model scored 86.1 on Terminal-Bench 2.1 and 56.0 on DeepSWE, compared with 85.0 and 59.0 for Claude Opus 4.8. It scored 86.0 on SWE-bench Verified, 92.8 on GPQA Diamond, and 80.0 on MCP-Atlas. The 35B MoE model activates 3B parameters per token and scored 68.5 on Terminal-Bench 2.1 using Claude Code and 79.0 on SWE-bench Verified. The 9B model scored 47.0 and 70.6 on those benchmarks, respectively; Ornith says its quantized Mobile version can run on iPhone and Android devices. Ornith reports that its benchmark results are averaged over five independent runs.
ornith.ai
11 min
8/19/2026
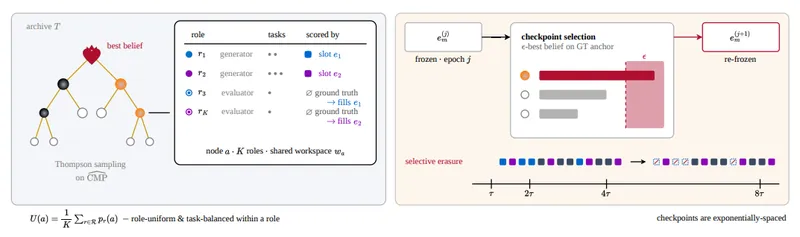
Red queen hypothesis – A new way forward for self-improving AI
Researchers from NVIDIA and Flower Labs have developed a method for recursive self-improving AI agents that allows them to enhance their own code without reaching an evaluation ceiling. This advancement addresses a significant challenge in the development of self-improving AI.
cst.cam.ac.uk
5 min
8/16/2026
Research papers using "kidney disappointment" instead of "kidney failure"
Google Scholar is a freely accessible web search engine that indexes the full text or metadata of scholarly literature across various formats. It provides a platform for researchers to find academic papers, theses, books, and conference proceedings.
scholar.google.com
1 min
8/16/2026
What happens when an LLM never sees material beyond fifth grade?
LittleLearner is a hosted 5B model designed for interactive use in a browser, allowing users to study knowledge acquisition in language models. It utilizes an 88B-token corpus filtered to the U.S. elementary-school curriculum, enabling controlled training and comparison with unfiltered models.
littlelearner-ll.github.io
3 min
8/16/2026
Semaglutide linked to 26% lower 5-year predicted dementia risk
Semaglutide is associated with a 26% reduction in the predicted risk of developing dementia over five years. This finding suggests potential cognitive benefits of the drug beyond its use for weight management and diabetes.
alz-journals.onlinelibrary.wiley.com
1 min
8/15/2026
Could a computer scientist build a brain?
A program is proposed to enable a single cell to build itself into a brain using only genomic information. The program must be compact enough to fit within a genome and efficient enough to complete development in a timely manner.
stankerstjens.github.io
36 min
8/15/2026
AI Model Atlas – visualizing populations of ML models as interconnected 3D graph
AI Model Atlas visualizes populations of machine learning models as interconnected 3D graphs. This tool facilitates the exploration and analysis of model relationships and performance.
run.cosmograph.app
1 min
8/14/2026
ElevenLabs, TwelveLabs, ThirteenLabs
A post titled “ElevenLabs, TwelveLabs, ThirteenLabs” was published on quantumi.sh and attributed to jemoka. The post had a score of 108 points and 41 comments at the time of the supplied data. The supplied text provides no further details about ElevenLabs, TwelveLabs, ThirteenLabs, their products, or any claims associated with them.
quantumi.sh
1 min
8/22/2026
DiffusionGemma Technical Report
DiffusionGemma is an experimental open-weight language model that generates text through discrete diffusion, refining 256-token blocks in parallel rather than producing tokens sequentially. The design is intended to avoid the decoding bottleneck of autoregressive language models. The model was created by fine-tuning the mixture-of-experts Gemma 4 model, which has 3.8 billion activated parameters and 25.2 billion total parameters. Its two-stage training process used fewer than 10% of the original autoregressive model’s total training-token budget. Supervised fine-tuning first taught bidirectional denoising; a second phase combined reinforcement learning and sampler distillation to improve generation quality and inference efficiency. Across its evaluation suite, DiffusionGemma generated about 20 tokens per forward pass and about 1,500 output tokens per second on a single Nvidia H100 GPU. The researchers say these results establish a new speed-capability trade-off frontier and exceed autoregressive models, including those using speculative decoding. DiffusionGemma retains Gemma 4’s thinking mode, multimodal-input, and long-context support. It can also still generate text autoregressively with minor performance degradation, suggesting potential hybrid diffusion-autoregressive decoding systems.
arxiv.org
2 min
8/20/2026
Red queen hypothesis – A new way forward for self-improving AI
Researchers from NVIDIA and Flower Labs have developed a method for recursive self-improving AI agents that allows them to enhance their own code without reaching an evaluation ceiling. This advancement addresses a significant challenge in the development of self-improving AI.
cst.cam.ac.uk
5 min
8/16/2026
What happens when an LLM never sees material beyond fifth grade?
LittleLearner is a hosted 5B model designed for interactive use in a browser, allowing users to study knowledge acquisition in language models. It utilizes an 88B-token corpus filtered to the U.S. elementary-school curriculum, enabling controlled training and comparison with unfiltered models.
littlelearner-ll.github.io
3 min
8/16/2026
Could a computer scientist build a brain?
A program is proposed to enable a single cell to build itself into a brain using only genomic information. The program must be compact enough to fit within a genome and efficient enough to complete development in a timely manner.
stankerstjens.github.io
36 min
8/15/2026
Micron announces $10B research hub in Boise
Micron Technology unveiled Micron Research Labs on August 20, 2026, a Boise-headquartered U.S. research institution focused on long-horizon advances in memory, computing and semiconductor manufacturing. The company plans to invest $10 billion in the labs over the next decade, funding a flagship Boise campus, university collaborations, global satellite labs and partnerships with government, startups, customers and other semiconductor-industry participants. Research will cover critical memory technologies, advanced memory and compute architectures, chip packaging, and future manufacturing methods. Micron said the institution will pursue work beyond current technology roadmaps and a 10-year horizon, while connecting its research operations across the United States, Europe, Japan, India, Singapore and Taiwan. The company expects to break ground on a facility capable of hosting hundreds of researchers in 2027; it is also expected to host conferences, workshops and innovation forums in Boise. The planned lab investment is separate from Micron’s previously announced commitment of more than $250 billion to U.S. manufacturing and research and development, which Micron says is expected to create more than 90,000 American jobs. Micron describes itself as the only U.S.-based company developing and manufacturing leading-edge memory.
investors.micron.com
9 min
8/21/2026
Ornith-1.5: From Self-Scaffolding to Self-Improvement
Ornith introduced Ornith-1.5, a family of 397B-parameter mixture-of-experts (MoE), 35B MoE, and 9B dense models trained through a self-improvement loop. The system generates progressively harder tasks, creates task-specific scaffolds containing instructions, tools, decomposition, and orchestration, then produces reinforcement-learning rollouts. Rewards optimize task generation, scaffold construction, and solutions jointly using validity, frontier difficulty, novelty, solution quality, and resistance to reward hacking. The target task success rate is 0.2, favoring problems difficult enough to expose capability gaps while still yielding successful training trajectories. Ornith reports that its 397B model scored 86.1 on Terminal-Bench 2.1 and 56.0 on DeepSWE, compared with 85.0 and 59.0 for Claude Opus 4.8. It scored 86.0 on SWE-bench Verified, 92.8 on GPQA Diamond, and 80.0 on MCP-Atlas. The 35B MoE model activates 3B parameters per token and scored 68.5 on Terminal-Bench 2.1 using Claude Code and 79.0 on SWE-bench Verified. The 9B model scored 47.0 and 70.6 on those benchmarks, respectively; Ornith says its quantized Mobile version can run on iPhone and Android devices. Ornith reports that its benchmark results are averaged over five independent runs.
ornith.ai
11 min
8/19/2026
Research papers using "kidney disappointment" instead of "kidney failure"
Google Scholar is a freely accessible web search engine that indexes the full text or metadata of scholarly literature across various formats. It provides a platform for researchers to find academic papers, theses, books, and conference proceedings.
scholar.google.com
1 min
8/16/2026
Semaglutide linked to 26% lower 5-year predicted dementia risk
Semaglutide is associated with a 26% reduction in the predicted risk of developing dementia over five years. This finding suggests potential cognitive benefits of the drug beyond its use for weight management and diabetes.
alz-journals.onlinelibrary.wiley.com
1 min
8/15/2026
AI Model Atlas – visualizing populations of ML models as interconnected 3D graph
AI Model Atlas visualizes populations of machine learning models as interconnected 3D graphs. This tool facilitates the exploration and analysis of model relationships and performance.
run.cosmograph.app
1 min
8/14/2026
ElevenLabs, TwelveLabs, ThirteenLabs
A post titled “ElevenLabs, TwelveLabs, ThirteenLabs” was published on quantumi.sh and attributed to jemoka. The post had a score of 108 points and 41 comments at the time of the supplied data. The supplied text provides no further details about ElevenLabs, TwelveLabs, ThirteenLabs, their products, or any claims associated with them.
quantumi.sh
1 min
8/22/2026
Ornith-1.5: From Self-Scaffolding to Self-Improvement
Ornith introduced Ornith-1.5, a family of 397B-parameter mixture-of-experts (MoE), 35B MoE, and 9B dense models trained through a self-improvement loop. The system generates progressively harder tasks, creates task-specific scaffolds containing instructions, tools, decomposition, and orchestration, then produces reinforcement-learning rollouts. Rewards optimize task generation, scaffold construction, and solutions jointly using validity, frontier difficulty, novelty, solution quality, and resistance to reward hacking. The target task success rate is 0.2, favoring problems difficult enough to expose capability gaps while still yielding successful training trajectories. Ornith reports that its 397B model scored 86.1 on Terminal-Bench 2.1 and 56.0 on DeepSWE, compared with 85.0 and 59.0 for Claude Opus 4.8. It scored 86.0 on SWE-bench Verified, 92.8 on GPQA Diamond, and 80.0 on MCP-Atlas. The 35B MoE model activates 3B parameters per token and scored 68.5 on Terminal-Bench 2.1 using Claude Code and 79.0 on SWE-bench Verified. The 9B model scored 47.0 and 70.6 on those benchmarks, respectively; Ornith says its quantized Mobile version can run on iPhone and Android devices. Ornith reports that its benchmark results are averaged over five independent runs.
ornith.ai
11 min
8/19/2026
What happens when an LLM never sees material beyond fifth grade?
LittleLearner is a hosted 5B model designed for interactive use in a browser, allowing users to study knowledge acquisition in language models. It utilizes an 88B-token corpus filtered to the U.S. elementary-school curriculum, enabling controlled training and comparison with unfiltered models.
littlelearner-ll.github.io
3 min
8/16/2026
AI Model Atlas – visualizing populations of ML models as interconnected 3D graph
AI Model Atlas visualizes populations of machine learning models as interconnected 3D graphs. This tool facilitates the exploration and analysis of model relationships and performance.
run.cosmograph.app
1 min
8/14/2026
Micron announces $10B research hub in Boise
Micron Technology unveiled Micron Research Labs on August 20, 2026, a Boise-headquartered U.S. research institution focused on long-horizon advances in memory, computing and semiconductor manufacturing. The company plans to invest $10 billion in the labs over the next decade, funding a flagship Boise campus, university collaborations, global satellite labs and partnerships with government, startups, customers and other semiconductor-industry participants. Research will cover critical memory technologies, advanced memory and compute architectures, chip packaging, and future manufacturing methods. Micron said the institution will pursue work beyond current technology roadmaps and a 10-year horizon, while connecting its research operations across the United States, Europe, Japan, India, Singapore and Taiwan. The company expects to break ground on a facility capable of hosting hundreds of researchers in 2027; it is also expected to host conferences, workshops and innovation forums in Boise. The planned lab investment is separate from Micron’s previously announced commitment of more than $250 billion to U.S. manufacturing and research and development, which Micron says is expected to create more than 90,000 American jobs. Micron describes itself as the only U.S.-based company developing and manufacturing leading-edge memory.
investors.micron.com
9 min
8/21/2026
Red queen hypothesis – A new way forward for self-improving AI
Researchers from NVIDIA and Flower Labs have developed a method for recursive self-improving AI agents that allows them to enhance their own code without reaching an evaluation ceiling. This advancement addresses a significant challenge in the development of self-improving AI.
cst.cam.ac.uk
5 min
8/16/2026
Semaglutide linked to 26% lower 5-year predicted dementia risk
Semaglutide is associated with a 26% reduction in the predicted risk of developing dementia over five years. This finding suggests potential cognitive benefits of the drug beyond its use for weight management and diabetes.
alz-journals.onlinelibrary.wiley.com
1 min
8/15/2026
DiffusionGemma Technical Report
DiffusionGemma is an experimental open-weight language model that generates text through discrete diffusion, refining 256-token blocks in parallel rather than producing tokens sequentially. The design is intended to avoid the decoding bottleneck of autoregressive language models. The model was created by fine-tuning the mixture-of-experts Gemma 4 model, which has 3.8 billion activated parameters and 25.2 billion total parameters. Its two-stage training process used fewer than 10% of the original autoregressive model’s total training-token budget. Supervised fine-tuning first taught bidirectional denoising; a second phase combined reinforcement learning and sampler distillation to improve generation quality and inference efficiency. Across its evaluation suite, DiffusionGemma generated about 20 tokens per forward pass and about 1,500 output tokens per second on a single Nvidia H100 GPU. The researchers say these results establish a new speed-capability trade-off frontier and exceed autoregressive models, including those using speculative decoding. DiffusionGemma retains Gemma 4’s thinking mode, multimodal-input, and long-context support. It can also still generate text autoregressively with minor performance degradation, suggesting potential hybrid diffusion-autoregressive decoding systems.
arxiv.org
2 min
8/20/2026
Research papers using "kidney disappointment" instead of "kidney failure"
Google Scholar is a freely accessible web search engine that indexes the full text or metadata of scholarly literature across various formats. It provides a platform for researchers to find academic papers, theses, books, and conference proceedings.
scholar.google.com
1 min
8/16/2026
Could a computer scientist build a brain?
A program is proposed to enable a single cell to build itself into a brain using only genomic information. The program must be compact enough to fit within a genome and efficient enough to complete development in a timely manner.
stankerstjens.github.io
36 min
8/15/2026