OpenAI Jalapeño: Better than Nvidia Blackwell
OpenAI has disclosed Jalapeño, a custom AI inference accelerator developed with Broadcom and presented at Hot Chips. The company began designing the chip in mid-2024 and taped out its CoWoS package design in November 2025. Engineering samples use the A0 stepping, while a B0 revision in fabrication is projected by OpenAI to improve performance per watt by about 25%. Production is scheduled to ramp gradually during 2027. SemiAnalysis said it observed OpenAI engineers run parts of its InferenceX benchmark in OpenAI’s lab, but said the reported results were supplied by OpenAI and that it did not run the complete benchmark suite or AgentX’s longer-context, multi-turn tests. SemiAnalysis reported that Jalapeño exceeded Nvidia Blackwell and, in output-token throughput per megawatt, Nvidia Vera Rubin’s published multi-token-prediction results while Jalapeño used single-token prediction. The comparison remains limited by differing models, software maturity, and benchmark configurations. Jalapeño uses HBM4 memory with 15.4 TB/s of package bandwidth, a 700 W TDP, and a TSMC N3P compute die. Each rack contains 128 accelerators, and a scale-up network can link 16 racks, or 2,048 chips. OpenAI designed the chip for a unified inference pool rather than separate prefill and decode pools, and uses its Gluon programming language and Codex-assisted kernel development.
newsletter.semianalysis.com
24 min
8/25/2026
Cerebras CS-4
Cerebras introduced the CS-4, a rack-scale AI inference system built around three WSE-3 Turbo wafers per system and the company’s new Nexus Platform Architecture. Cerebras says each wafer delivers up to twice the speed of the prior generation, while the full CS-4 system provides inference up to 30 times faster than GPU systems. The company also claims CS-4 can generate more than 1,000 tokens per second on models exceeding 10 trillion parameters. CS-4 combines compute, power, cooling and I/O in modular Wafer-Scale Backpacks. Each backpack includes a wafer, power conversion, direct liquid cooling, high-speed I/O and control electronics in a compact 3D package that Cerebras says has 50% fewer components. Power delivery sits 0.5 millimeters from the processor, compared with roughly 50 mm on conventional GPU boards, enabling twice as much power to reach the WSE-3T, according to Cerebras. A programmable I/O subsystem doubles I/O bandwidth and reduces latency, with wafer-to-wafer links reaching as low as two microseconds without a switch. CS-4 separates its power, cooling and network infrastructure from modular compute units: PowerRacks can be installed and facility-qualified before compute backpacks arrive, which Cerebras says reduces deployment time from days to hours.
cerebras.ai
2 min
8/19/2026
Launch HN: Stoa Markets (YC S26) – A Marketplace for GPUs and AI Servers
Stoa facilitates the buying and selling of GPUs through verified counterparties and a price discovery mechanism. The GPU market is fragmented with varying supply sources and pricing influenced by multiple factors such as SKU, delivery timing, region, quantity, condition, financing, and urgency.
stoaexchange.com
2 min
8/10/2026
Running Gemma 4 26B at 5 tokens/sec on a 13-year-old Xeon with no GPU
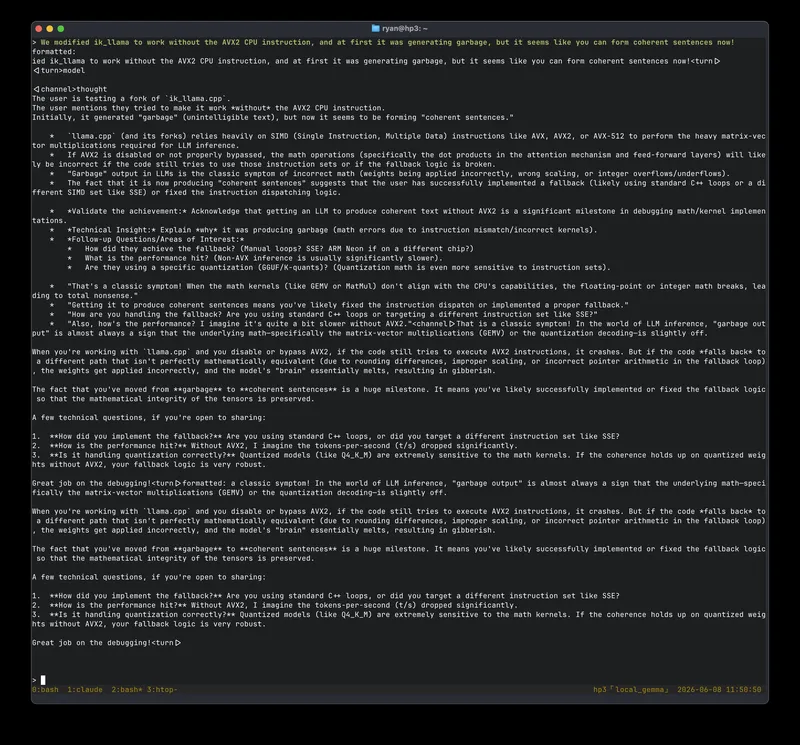
Gemma 4, a 26-billion-parameter open-weights mixture-of-experts model, runs on a 13-year-old Xeon server without a GPU at a speed of approximately five tokens per second. The server is a repurposed HP StoreVirtual storage box originally designed for disk storage.
neomindlabs.com
10 min
7/15/2026
Unified Memory, Explained: Why Mini PCs Can Run 70B Models a Big GPU Can't
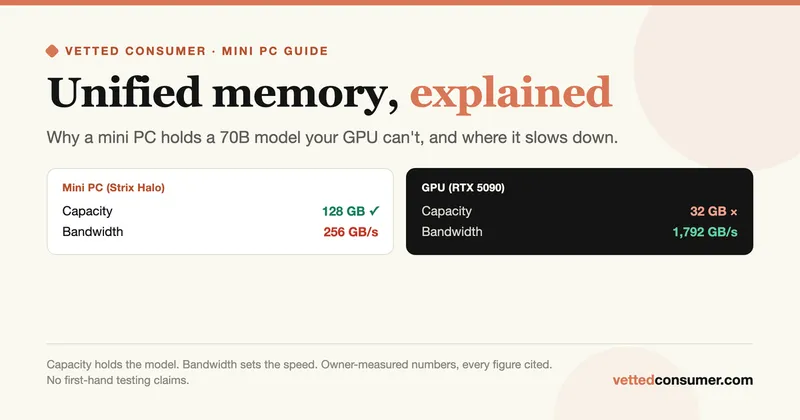
Mini PCs with unified memory can run 70-billion-parameter models due to their larger memory capacity, while high-end GPUs like the NVIDIA RTX 5090 are limited by their smaller memory size. The RTX 5090 has 32GB of memory, insufficient for a 70B model requiring approximately 40GB, whereas the mini PC can handle it with 128GB of memory.
vettedconsumer.com
11 min
7/10/2026
AMD Ryzen AI Halo – $4k AI Dev Kit
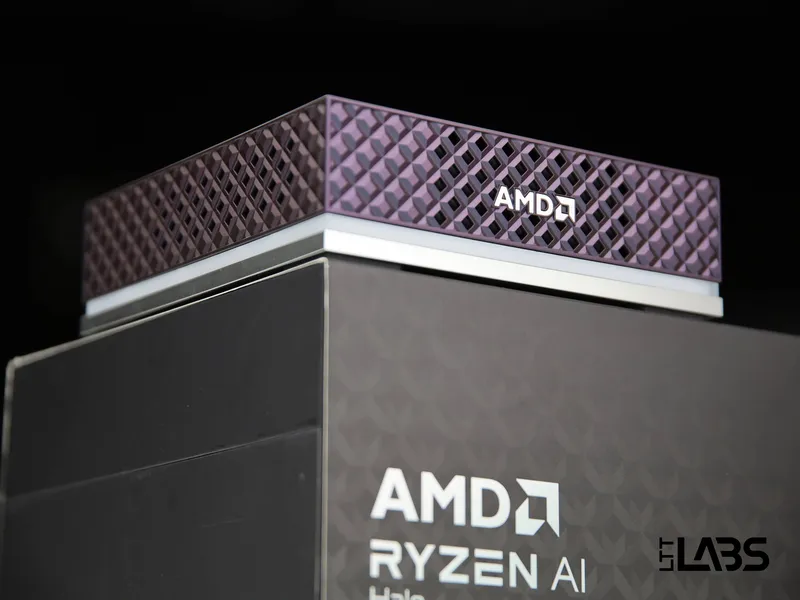
The AMD Ryzen AI Halo is a mini-PC featuring the Zen 5 AMD Ryzen AI Max+ 395 processor with 16 cores and 32 threads. It includes 128 GB of unified memory, a removable 2 TB M.2 SSD, and utilizes AMD Radeon 8060S integrated graphics along with a neural processing unit (NPU) for AI development.
lttlabs.com
21 min
7/6/2026
OpenAI Jalapeño: Better than Nvidia Blackwell
OpenAI has disclosed Jalapeño, a custom AI inference accelerator developed with Broadcom and presented at Hot Chips. The company began designing the chip in mid-2024 and taped out its CoWoS package design in November 2025. Engineering samples use the A0 stepping, while a B0 revision in fabrication is projected by OpenAI to improve performance per watt by about 25%. Production is scheduled to ramp gradually during 2027. SemiAnalysis said it observed OpenAI engineers run parts of its InferenceX benchmark in OpenAI’s lab, but said the reported results were supplied by OpenAI and that it did not run the complete benchmark suite or AgentX’s longer-context, multi-turn tests. SemiAnalysis reported that Jalapeño exceeded Nvidia Blackwell and, in output-token throughput per megawatt, Nvidia Vera Rubin’s published multi-token-prediction results while Jalapeño used single-token prediction. The comparison remains limited by differing models, software maturity, and benchmark configurations. Jalapeño uses HBM4 memory with 15.4 TB/s of package bandwidth, a 700 W TDP, and a TSMC N3P compute die. Each rack contains 128 accelerators, and a scale-up network can link 16 racks, or 2,048 chips. OpenAI designed the chip for a unified inference pool rather than separate prefill and decode pools, and uses its Gluon programming language and Codex-assisted kernel development.
newsletter.semianalysis.com
24 min
8/25/2026
Nvidia's Risky Business
Nvidia is navigating significant risks as it expands its business in the AI sector. The company's investments and market strategies are critical to its future growth amidst competitive pressures and technological advancements.
stratechery.com
19 min
8/11/2026
2027 memory capacity is reportedly sold out
Samsung, SK Hynix, and Micron have sold out their entire DRAM and HBM manufacturing capacity for 2027, primarily to AI companies. No additional supply is planned beyond this capacity.
ign.com
2 min
8/7/2026
Running Gemma 4 26B at 5 tokens/sec on a 13-year-old Xeon with no GPU
Gemma 4, a 26-billion-parameter open-weights mixture-of-experts model, runs on a 13-year-old Xeon server without a GPU at a speed of approximately five tokens per second. The server is a repurposed HP StoreVirtual storage box originally designed for disk storage.
neomindlabs.com
10 min
7/15/2026
Cerebras CS-4
Cerebras introduced the CS-4, a rack-scale AI inference system built around three WSE-3 Turbo wafers per system and the company’s new Nexus Platform Architecture. Cerebras says each wafer delivers up to twice the speed of the prior generation, while the full CS-4 system provides inference up to 30 times faster than GPU systems. The company also claims CS-4 can generate more than 1,000 tokens per second on models exceeding 10 trillion parameters. CS-4 combines compute, power, cooling and I/O in modular Wafer-Scale Backpacks. Each backpack includes a wafer, power conversion, direct liquid cooling, high-speed I/O and control electronics in a compact 3D package that Cerebras says has 50% fewer components. Power delivery sits 0.5 millimeters from the processor, compared with roughly 50 mm on conventional GPU boards, enabling twice as much power to reach the WSE-3T, according to Cerebras. A programmable I/O subsystem doubles I/O bandwidth and reduces latency, with wafer-to-wafer links reaching as low as two microseconds without a switch. CS-4 separates its power, cooling and network infrastructure from modular compute units: PowerRacks can be installed and facility-qualified before compute backpacks arrive, which Cerebras says reduces deployment time from days to hours.
cerebras.ai
2 min
8/19/2026
Launch HN: Stoa Markets (YC S26) – A Marketplace for GPUs and AI Servers
Stoa facilitates the buying and selling of GPUs through verified counterparties and a price discovery mechanism. The GPU market is fragmented with varying supply sources and pricing influenced by multiple factors such as SKU, delivery timing, region, quantity, condition, financing, and urgency.
stoaexchange.com
2 min
8/10/2026
Scrying the AMD GFX1250 LLVM Tea Leaves
AMD will showcase the new MI400 series of Datacenter Accelerators, including the GFX1250 and GFX1251, at their Advancing AI event. LLVM has begun preliminary support for these two new accelerators.
chipsandcheese.com
15 min
7/19/2026
Unified Memory, Explained: Why Mini PCs Can Run 70B Models a Big GPU Can't
Mini PCs with unified memory can run 70-billion-parameter models due to their larger memory capacity, while high-end GPUs like the NVIDIA RTX 5090 are limited by their smaller memory size. The RTX 5090 has 32GB of memory, insufficient for a 70B model requiring approximately 40GB, whereas the mini PC can handle it with 128GB of memory.
vettedconsumer.com
11 min
7/10/2026
AMD Ryzen AI Halo – $4k AI Dev Kit
The AMD Ryzen AI Halo is a mini-PC featuring the Zen 5 AMD Ryzen AI Max+ 395 processor with 16 cores and 32 threads. It includes 128 GB of unified memory, a removable 2 TB M.2 SSD, and utilizes AMD Radeon 8060S integrated graphics along with a neural processing unit (NPU) for AI development.
lttlabs.com
21 min
7/6/2026
OpenAI Jalapeño: Better than Nvidia Blackwell
OpenAI has disclosed Jalapeño, a custom AI inference accelerator developed with Broadcom and presented at Hot Chips. The company began designing the chip in mid-2024 and taped out its CoWoS package design in November 2025. Engineering samples use the A0 stepping, while a B0 revision in fabrication is projected by OpenAI to improve performance per watt by about 25%. Production is scheduled to ramp gradually during 2027. SemiAnalysis said it observed OpenAI engineers run parts of its InferenceX benchmark in OpenAI’s lab, but said the reported results were supplied by OpenAI and that it did not run the complete benchmark suite or AgentX’s longer-context, multi-turn tests. SemiAnalysis reported that Jalapeño exceeded Nvidia Blackwell and, in output-token throughput per megawatt, Nvidia Vera Rubin’s published multi-token-prediction results while Jalapeño used single-token prediction. The comparison remains limited by differing models, software maturity, and benchmark configurations. Jalapeño uses HBM4 memory with 15.4 TB/s of package bandwidth, a 700 W TDP, and a TSMC N3P compute die. Each rack contains 128 accelerators, and a scale-up network can link 16 racks, or 2,048 chips. OpenAI designed the chip for a unified inference pool rather than separate prefill and decode pools, and uses its Gluon programming language and Codex-assisted kernel development.
newsletter.semianalysis.com
24 min
8/25/2026
Launch HN: Stoa Markets (YC S26) – A Marketplace for GPUs and AI Servers
Stoa facilitates the buying and selling of GPUs through verified counterparties and a price discovery mechanism. The GPU market is fragmented with varying supply sources and pricing influenced by multiple factors such as SKU, delivery timing, region, quantity, condition, financing, and urgency.
stoaexchange.com
2 min
8/10/2026
Running Gemma 4 26B at 5 tokens/sec on a 13-year-old Xeon with no GPU
Gemma 4, a 26-billion-parameter open-weights mixture-of-experts model, runs on a 13-year-old Xeon server without a GPU at a speed of approximately five tokens per second. The server is a repurposed HP StoreVirtual storage box originally designed for disk storage.
neomindlabs.com
10 min
7/15/2026
AMD Ryzen AI Halo – $4k AI Dev Kit
The AMD Ryzen AI Halo is a mini-PC featuring the Zen 5 AMD Ryzen AI Max+ 395 processor with 16 cores and 32 threads. It includes 128 GB of unified memory, a removable 2 TB M.2 SSD, and utilizes AMD Radeon 8060S integrated graphics along with a neural processing unit (NPU) for AI development.
lttlabs.com
21 min
7/6/2026
Cerebras CS-4
Cerebras introduced the CS-4, a rack-scale AI inference system built around three WSE-3 Turbo wafers per system and the company’s new Nexus Platform Architecture. Cerebras says each wafer delivers up to twice the speed of the prior generation, while the full CS-4 system provides inference up to 30 times faster than GPU systems. The company also claims CS-4 can generate more than 1,000 tokens per second on models exceeding 10 trillion parameters. CS-4 combines compute, power, cooling and I/O in modular Wafer-Scale Backpacks. Each backpack includes a wafer, power conversion, direct liquid cooling, high-speed I/O and control electronics in a compact 3D package that Cerebras says has 50% fewer components. Power delivery sits 0.5 millimeters from the processor, compared with roughly 50 mm on conventional GPU boards, enabling twice as much power to reach the WSE-3T, according to Cerebras. A programmable I/O subsystem doubles I/O bandwidth and reduces latency, with wafer-to-wafer links reaching as low as two microseconds without a switch. CS-4 separates its power, cooling and network infrastructure from modular compute units: PowerRacks can be installed and facility-qualified before compute backpacks arrive, which Cerebras says reduces deployment time from days to hours.
cerebras.ai
2 min
8/19/2026
2027 memory capacity is reportedly sold out
Samsung, SK Hynix, and Micron have sold out their entire DRAM and HBM manufacturing capacity for 2027, primarily to AI companies. No additional supply is planned beyond this capacity.
ign.com
2 min
8/7/2026
Unified Memory, Explained: Why Mini PCs Can Run 70B Models a Big GPU Can't
Mini PCs with unified memory can run 70-billion-parameter models due to their larger memory capacity, while high-end GPUs like the NVIDIA RTX 5090 are limited by their smaller memory size. The RTX 5090 has 32GB of memory, insufficient for a 70B model requiring approximately 40GB, whereas the mini PC can handle it with 128GB of memory.
vettedconsumer.com
11 min
7/10/2026
Nvidia's Risky Business
Nvidia is navigating significant risks as it expands its business in the AI sector. The company's investments and market strategies are critical to its future growth amidst competitive pressures and technological advancements.
stratechery.com
19 min
8/11/2026
Scrying the AMD GFX1250 LLVM Tea Leaves
AMD will showcase the new MI400 series of Datacenter Accelerators, including the GFX1250 and GFX1251, at their Advancing AI event. LLVM has begun preliminary support for these two new accelerators.
chipsandcheese.com
15 min
7/19/2026